

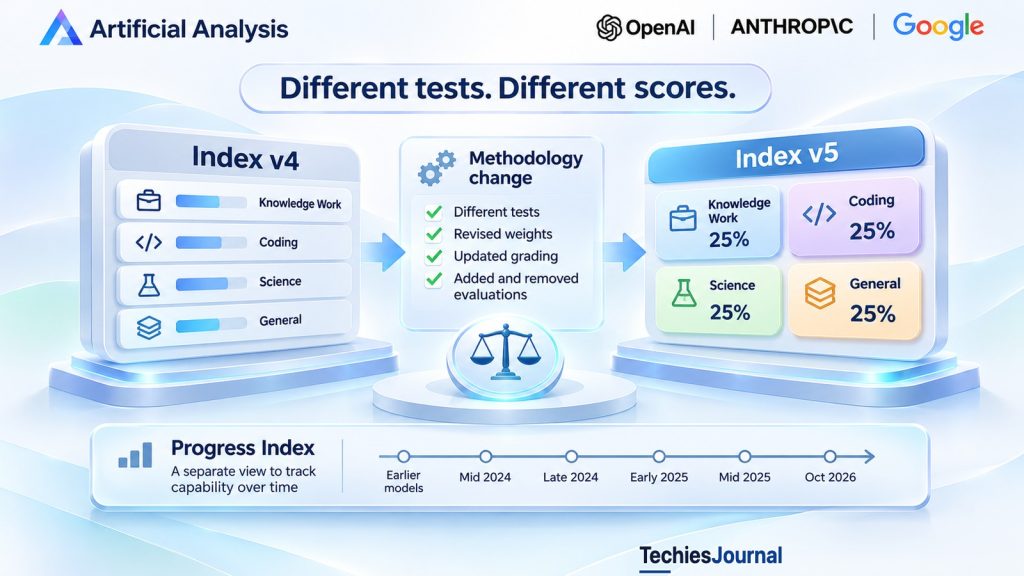
Artificial Analysis rebuilt its Intelligence Index in October 2026, changing the tests and weights used to compare AI models. The update explains why a model’s score can move even when the model itself has not changed.
Imagine a development team reviewing two AI model evaluation reports.
The first gives a model a score of 55. A newer report gives the same model version a score of 50.
Nothing about the model has necessarily changed, yet the team now sees a lower number.
Has the model become less capable, or has the measurement changed?
These numbers are hypothetical. They illustrate a question made particularly relevant on October 27, 2026, when Artificial Analysis released version 5 of its Intelligence Index.
The organization changed the evaluations used in its composite benchmark, introduced new tests, upgraded existing ones and revised how capabilities contribute to the final score.
According to Artificial Analysis, 60% of the updated index’s weight comes from evaluations using private test sets or held-out answers.
The company also introduced a separate Progress Index to estimate how model capabilities have changed over time.
These changes affect what a reported score represents.
For anyone choosing AI models, the essential distinction is between a change in model performance and a change in how that performance is measured.
What changed in Intelligence Index v5?
The Artificial Analysis Intelligence Index combines results from several evaluations into one composite score.
Version 5 organizes nine evaluations into four equally weighted categories.
| Category | Index weight | Evaluations |
|---|---|---|
| Knowledge Work | 25% | AA-Briefcase, AutomationBench-AA, GDP.pdf |
| Coding | 25% | FrontierCode 2.0, Terminal-Bench 4.0 |
| Science | 25% | Terminal-Bench-Science, CritPt v2 hard subset |
| General | 25% | AA-Omniscience v1.1, HLE-Diamond |
The individual evaluations are not weighted equally within each category.
For example, FrontierCode 2.0 contributes 15% of the overall index, while Terminal-Bench 4.0 contributes 10%.
Artificial Analysis described the October release as its biggest upgrade since v4 launched in January.
Two evaluations were added.
FrontierCode 2.0 tests coding agents against 132 tasks involving open-source repositories. Its assessment considers whether a maintainer would accept the change, rather than relying solely on whether automated tests pass. A failed blocking check can reduce the task score to zero.
Terminal-Bench-Science introduces 70 scientific research tasks conducted through a terminal environment. A task passes only when every required test passes.
Three evaluations were upgraded.
HLE-Diamond replaced the original Humanity’s Last Exam component with a refined set of 1,000 questions.
AA-Omniscience v1.1 revised its dataset to remove public or saturated questions and address ambiguous or erroneous items.
CritPt v2 entered the index through a private 40-question hard subset of a physics evaluation, with access to code execution.
The composite also removed GDPval-AA v2.1, SciCode and AA-LCR v1.1.
The consequences are technical, not cosmetic. A score produced by v5 reflects a different collection of tasks, grading conditions and weights from the preceding version.
Added
FrontierCode 2.0 tests coding agents against 132 tasks involving open-source repositories. Its assessment considers whether a maintainer would accept the change, rather than relying solely on whether automated tests pass. A failed blocking check can reduce the task score to zero.
Terminal-Bench-Science introduces 70 scientific research tasks conducted through a terminal environment. A task passes only when every required test passes.
Upgraded
HLE-Diamond replaced the original Humanity’s Last Exam component with a refined set of 1,000 questions.
AA-Omniscience v1.1 revised its dataset to remove public or saturated questions and address ambiguous or erroneous items.
CritPt v2 entered the index through a private 40-question hard subset of a physics evaluation, with access to code execution.
Removed
The composite also removed GDPval-AA v2.1, SciCode and AA-LCR v1.1.
The consequences are technical, not cosmetic. A score produced by v5 reflects a different collection of tasks, grading conditions and weights from the preceding version.
Source: Artificial Analysis, Announcing Artificial Analysis Intelligence Index v5, October 27, 2026
How can the same model receive a different score?
Return to the hypothetical development team.
Its model version is unchanged, but the evaluation suite is different.
An older benchmark might emphasize short coding exercises. A newer benchmark might place greater weight on modifying complex repositories and satisfying several acceptance conditions.
A model can be effective at the first type of task while struggling with the second.
That difference does not necessarily represent a decline in the model’s underlying capabilities.
It can represent a change in what the evaluator asks the model to do.
The grading method also matters.
Suppose a coding agent completes most of a requested change but fails one critical requirement.
An evaluation awarding partial credit may recognize the successful work. Another may assign zero because the failure makes the change unacceptable.
FrontierCode 2.0 uses blocking checks that can produce a zero score for an attempt.
A model’s performance under this stricter acceptance standard tells readers something useful about its behavior. It does not establish that its score on an earlier, differently graded task would have fallen.
Weighting produces another effect.
If a model is relatively strong in science but weaker in repository-based coding, increasing the importance of coding tasks can change its composite result.
This is why a composite benchmark should not be understood as a permanent, universal measurement of intelligence.
It summarizes performance on a particular selection of tasks under defined evaluation conditions.
The question
A team sees a score of 55 in one evaluation report and 50 in a newer report for the same model version. Has the model become less capable, or has the measurement changed? These numbers are hypothetical.
Task mix
An older benchmark might emphasize short coding exercises. A newer benchmark might place greater weight on modifying complex repositories and satisfying several acceptance conditions. A model can be effective at the first type of task while struggling with the second. That does not necessarily represent a decline in the model’s underlying capabilities.
Grading
An evaluation awarding partial credit may recognize successful work. Another may assign zero because one critical requirement failed. FrontierCode 2.0 uses blocking checks that can produce a zero score for an attempt.
Weights
If a model is relatively strong in science but weaker in repository-based coding, increasing the importance of coding tasks can change its composite result.
What does a more private evaluation improve?
Artificial Analysis reports that 60% of the v5 index weight comes from evaluations using private test sets or held-out answers.
This addresses a genuine evaluation problem.
Public benchmarks allow researchers to inspect questions, understand grading rules and reproduce results.
But public availability also creates opportunities for test material to appear in training data, prompts or model-development feedback.
A model familiar with benchmark questions may perform well partly because of prior exposure, rather than because it can solve equally difficult unfamiliar problems.
Keeping test tasks or answers private is intended to reduce that risk.
FrontierCode 2.0 uses private repository tasks. AA-Omniscience v1.1 also removes questions described by the publisher as public or insufficiently discriminating.
These measures may make known-answer exposure more difficult.
However, private does not mean contamination-proof.
The published methodology explains the evaluator’s design choices. It does not independently establish that no model has encountered related material.
Private tests also create a trade-off.
When tasks and grading details are withheld, outside researchers have less information with which to reproduce or challenge individual results.
The approach can reduce some exposure risks while increasing dependence on the benchmark publisher’s task selection, grading implementation and quality controls.
Neither a fully public nor a partly private benchmark automatically provides a complete measure of real-world model reliability.
Improves
Public availability creates opportunities for test material to appear in training data, prompts or model-development feedback. A model familiar with benchmark questions may perform well partly because of prior exposure. Keeping test tasks or answers private is intended to reduce that risk.
Costs
When tasks and grading details are withheld, outside researchers have less information with which to reproduce or challenge individual results. The approach can reduce some exposure risks while increasing dependence on the benchmark publisher’s task selection, grading implementation and quality controls.
Not proven
Private does not mean contamination-proof. The published methodology explains the evaluator’s design choices. It does not independently establish that no model has encountered related material.
Practical tasks are useful, but still selective
Intelligence Index v5 gives substantial weight to evaluations involving tools, repositories and multistep work.
That is useful because many professional applications require more than producing an isolated answer.
Nevertheless, an evaluation resembling practical work is not automatically representative of every organization’s environment.
FrontierCode tests changes in selected repositories. A development team maintaining a private enterprise application may have different programming languages, architecture, security constraints and review requirements.
Terminal-Bench-Science tests research workflows under specified terminal conditions. It does not establish that a model can reliably complete every scientific workflow.
Artificial Analysis also describes its Intelligence Index as primarily text-based and English-language. It reports broader multilingual and other modalities through separate evaluations.
The distinction is between measuring the chosen tasks and predicting performance on tasks outside the evaluation.
The October changes may improve the publisher’s ability to distinguish among current models. Whether they predict success in a particular business application requires additional evidence from that application.
Why v4 and v5 scores are not directly comparable
A benchmark score has meaning only within the measurement method that produced it.
When the task selection, scoring rules or weights change, the numerical scale may change too.
For the hypothetical model whose score moved from 55 to 50, reporting a five-point capability decline would therefore be unsupported.
The difference might result from harder tasks, different weightings, stricter grading or changed evaluation conditions.
Even a change in ranking can reflect the fact that different models respond differently to the revised task mix.
Artificial Analysis states that successive Intelligence Index versions are not intended to form one directly comparable long-term capability scale.
An Intelligence Index v5 score describes performance under the v5 framework.
An earlier v4 score describes performance under the earlier framework.
Both can be useful without being suitable for direct subtraction.
Source: Artificial Analysis, Progress Index v1 Methodology, October 2026
What does the separate Progress Index measure?
To address historical comparisons, Artificial Analysis introduced Progress Index v1 alongside the October update.
The Intelligence Index and Progress Index serve different purposes.
The Intelligence Index is designed to compare current models against tasks selected to represent contemporary capabilities.
Its composition can change when models improve and older evaluations stop distinguishing among them.
The Progress Index instead attempts to estimate model capability over time on a shared statistical scale.
It uses a method called item response theory.
The central idea is to estimate model capability and task difficulty together.
A model that succeeds on relatively difficult tasks provides different evidence from one that succeeds only on easier tasks.
The statistical method considers those results when estimating where models belong on a common scale.
Importantly, models do not all need to complete exactly the same tasks.
Artificial Analysis connects benchmarks through models that have been evaluated across multiple benchmarks. It uses individual task results where suitable data are available and aggregate benchmark results otherwise.
Those overlapping model results help place older and newer evaluations on the shared estimated scale.
This is more appropriate for studying historical trends than subtracting scores from different Intelligence Index versions.
But it remains an estimate.
The resulting positions depend on the available evaluation data, the statistical model and its assumptions. They are not equivalent to observing every model complete an identical set of tasks under identical conditions.
Together
The Progress Index uses a method called item response theory. The central idea is to estimate model capability and task difficulty together. A model that succeeds on relatively difficult tasks provides different evidence from one that succeeds only on easier tasks.
Not the same tasks
Models do not all need to complete exactly the same tasks.
Linked
Artificial Analysis connects benchmarks through models that have been evaluated across multiple benchmarks. It uses individual task results where suitable data are available and aggregate benchmark results otherwise. Those overlapping model results help place older and newer evaluations on the shared estimated scale.
An estimate
It remains an estimate. The resulting positions depend on the available evaluation data, the statistical model and its assumptions. They are not equivalent to observing every model complete an identical set of tasks under identical conditions.
Artificial Analysis recommends the Intelligence Index for comparing current models and the Progress Index for examining capability over time.
Source: Artificial Analysis, Progress Index v1 Methodology, October 2026
Model settings can change the result too
Benchmark methodology is not the only variable that matters.
The same model can be evaluated under different reasoning-effort settings.
In its October 27 announcement, Artificial Analysis reported that Claude Opus 5.5 scored 35 at low effort and 58 at maximum effort.
The estimated cost per Intelligence Index task also rose from $0.98 to $10.04.
These are results reported by Artificial Analysis, not independently reproduced measurements by TechiesJournal.
Low effort
In its October 27 announcement, Artificial Analysis reported that Claude Opus 5.5 scored 35 at low effort. The estimated cost per Intelligence Index task was $0.98.
Maximum effort
At maximum effort the same model scored 58, and the estimated cost per Intelligence Index task rose to $10.04.
Why it matters
These are results reported by Artificial Analysis, not independently reproduced measurements by TechiesJournal. A benchmark score belongs to a model version and its evaluation configuration, rather than to a product name alone. A higher score may be valuable, but the additional computation and cost matter when assessing operational suitability.
They illustrate why a benchmark score belongs to a model version and its evaluation configuration, rather than to a product name alone.
The available tools, prompting, effort settings and execution conditions can all affect observed performance.
A higher score may be valuable, but the additional computation and cost matter when assessing operational suitability.
How should a team use a revised benchmark?
A development team reviewing a new model ranking should establish four things before treating a score movement as meaningful.
First, check the benchmark version. Scores from different methodology versions may not be directly comparable.
Second, examine what the evaluation measures. Identify the tasks, grading conditions and weights, then assess how closely they resemble the team’s intended application.
Third, check the model configuration. A result obtained at maximum reasoning effort should not be assumed to describe a cheaper, lower-effort deployment.
Fourth, choose the right comparison. Use a current-version evaluation to compare models under that evaluation’s conditions. Use a documented historical methodology, such as the Progress Index, when studying longer-term trends.
Version
Check the benchmark version. Scores from different methodology versions may not be directly comparable.
What it measures
Examine what the evaluation measures. Identify the tasks, grading conditions and weights, then assess how closely they resemble the team’s intended application.
Configuration
Check the model configuration. A result obtained at maximum reasoning effort should not be assumed to describe a cheaper, lower-effort deployment.
Comparison
Choose the right comparison. Use a current-version evaluation to compare models under that evaluation’s conditions. Use a documented historical methodology, such as the Progress Index, when studying longer-term trends.
Public evaluations can help a team decide which models deserve further testing.
The final operational decision should also consider representative tasks, failure severity, consistency, cost, latency and the organization’s own constraints.
These are complementary kinds of evidence.
The benchmark changed. What should change in the decision?
Artificial Analysis Intelligence Index v5 is a substantive methodology revision.
It changes the mix of evaluated capabilities, introduces stricter task assessments, revises weights and increases reliance on private or held-out evaluation material.
Those choices may make the index more informative about the capabilities its publisher wants to measure today. They do not prove that it predicts every production workload more accurately.
The separate Progress Index addresses a different question by estimating historical capability on a shared scale, with the limitations inherent in statistical estimation.
For teams selecting AI models, a changed score should trigger a check of the measurement conditions before a conclusion about model progress or decline.
A benchmark result tells us how a model performed under defined conditions. A change in that result does not tell us why it changed until the conditions are understood.
References and further reading
- Artificial Analysis, Announcing Artificial Analysis Intelligence Index v5. October 27, 2026. Primary announcement of the new evaluations, revisions and updated weights.
- Artificial Analysis, Intelligence Benchmarking Methodology. Version 5.0.1 displayed during the November 3, 2026 review.
- Artificial Analysis, Progress Index v1 Methodology. October 2026. Statistical approach to estimating capability across different evaluation sets.
- TechiesJournal, Benchmark Theatre: How to Read AI Model Claims. September 2026. Related reading on interpreting benchmark claims and selecting models.
Evidence cutoff: November 3, 2026. The methodology, evaluation roster and reported rankings may change. This article describes the October 27 v5 release and identifies the methodology version visible during review.