

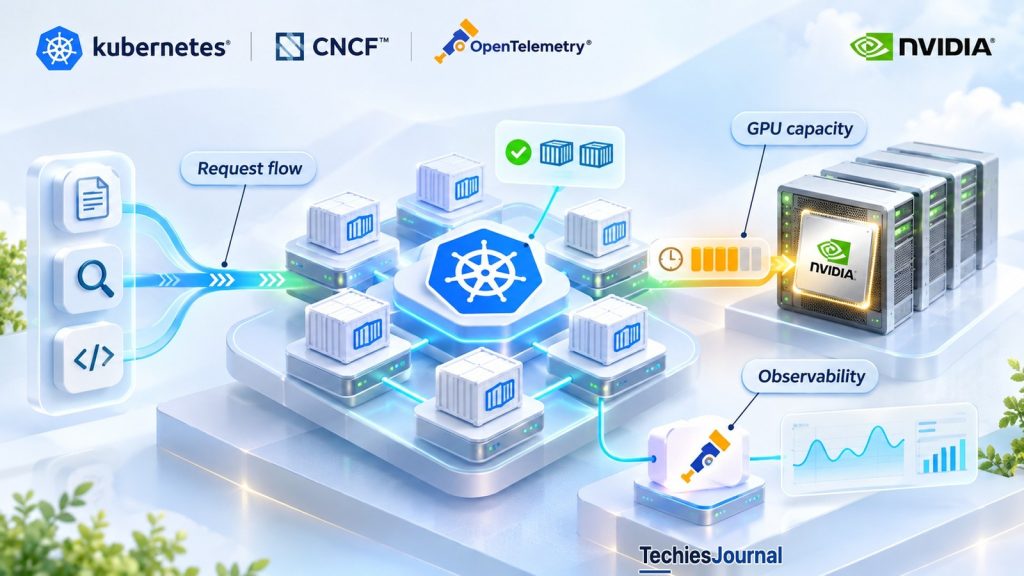
As organizations put AI into production, Kubernetes is becoming a familiar home for the services around it. But an application can be running while users still wait for answers. The difference changes how platform teams investigate performance, allocate GPUs and plan reliable service.
Editorial illustration: The company and incident in this article are fictional. Technical explanations and industry statistics are supported by the linked sources.
Everything is running, but employees are waiting
The company’s new AI assistant looked successful. Employees could ask questions about internal policies and technical documents instead of searching multiple websites. The pilot returned useful answers within seconds. Its developers packaged the software into containers and deployed it to the company’s existing Kubernetes platform.
Then the assistant became available to thousands of employees. Some answers arrived quickly. Others took so long that people gave up.
Operations engineers inspected the cluster. The nodes were available, the application’s containers were running, and Kubernetes had maintained the expected number of copies. Yet the service felt broken.
Adding another application server seemed like the obvious response. But that would cost money without answering a more important question: Where was each request spending its time?
The problem reflects a wider change. In its 2025 Annual Cloud Native Survey, published in January 2026, CNCF reported that 82% of surveyed container users operated Kubernetes in production.
In a separate survey question answered by 213 organizations hosting AI workloads, 66% used Kubernetes for some or all inference workloads. Those figures describe different respondent groups, not all companies worldwide. CNCF also introduced a dedicated AI Inference + Agentic track at KubeCon North America 2026.
AI is entering infrastructure that platform teams already know. The mystery is why familiar tools do not always tell the full story.
Follow one question through the system
The engineers select a delayed request: an employee has asked what changed in the travel reimbursement policy.
The assistant first checks the employee’s permission to view the policy. It searches company documents, selects relevant passages, and sends the question and supporting text to a language model. The model generates an answer. Finding supporting information before generation is commonly called retrieval-augmented generation (RAG). Using an already trained model to produce an answer is inference.
Kubernetes can operate the software behind those steps. A container packages an application and its software dependencies.
Kubernetes schedules containers in Pods, the units it places on worker machines called nodes. It can maintain requested copies and replace failed Pods when suitable resources are available. The official Kubernetes overview explains the orchestration model.
But the assistant does not run as a single indivisible service. Its request passes through several stages:
| Request stage | Work being done | Possible delay |
|---|---|---|
| Identity | Check the employee’s access | Identity-service response |
| Retrieval | Search indexed policy documents | Search or storage latency |
| Inference | Generate an answer using the language model | Waiting for model capacity and generation time |
| Return | Deliver the answer to the application | Network or application delay |
In our illustrative investigation, the identity and retrieval services respond quickly. The requests pile up at inference.
The application API accepts questions faster than the model can complete them, creating a queue. More API Pods would simply feed the same queue faster. The engineers have located the bottleneck. Now they need to understand the resource behind it.
An available CPU is not an available GPU
Ordinary web services often depend primarily on a CPU, the general-purpose processor that runs application code, and memory for active data. Large language models frequently use GPUs, processors suited to many parallel mathematical operations. GPUs also need enough dedicated memory to hold model data and handle requests. Not every AI service needs its own GPU: smaller models can run on CPUs, and many applications call a hosted model instead.
Our company chose to host a GPU-backed model. Imagine it has four suitable GPUs and all four are already allocated to model-serving workloads. Kubernetes may have spare CPU and memory for another API Pod, but an additional model replica needs a suitable GPU. The replica can remain unscheduled even while the cluster appears to have plenty of ordinary computing capacity.
Kubernetes learns about GPUs through device plugins and can use Dynamic Resource Allocation (DRA) to let workloads request device characteristics through resource claims. DRA has been stable since Kubernetes 1.35.
Crucially, the DRA documentation says the scheduler cannot preempt an existing Pod using DRA resources to give that device to a higher-priority Pod. The urgent Pod can remain pending until the device becomes free. Device sharing is possible in supported configurations. The four-GPU example is only a simplified illustration, not a universal rule of one workload per GPU.
This is the point at which the team’s old scaling instinct fails: creating more software copies cannot manufacture a scarce accelerator.
What the investigation changed
| Earlier assumption | Evidence from the request |
|---|---|
| The containers are healthy, so the assistant is healthy | Users still wait for model inference |
| More API replicas will fix the delay | The API is not the constrained component |
| Idle server CPU means there is capacity | Suitable GPU memory/devices may already be allocated |
| Priority guarantees immediate recovery capacity | DRA scheduling has a documented preemption limitation |
The engineers no longer need another explanation of the failure. They need to choose an intervention and test its consequences.
Fix capacity, visibility and recovery
Start with inference demand, not API CPU usage. The team measures requests waiting for the model, requests currently being processed, response latency and model-serving throughput. KServe is an open-source platform for serving models on Kubernetes. Its generative-inference autoscaling documentation shows how KEDA (Kubernetes Event-driven Autoscaling) can scale inference replicas using model-serving metrics, including request counts from the vLLM inference engine, with the necessary metrics infrastructure configured.
That scaling can request more replicas, but it cannot guarantee GPU availability. The team must decide whether reserving accelerators, improving batching (grouping requests so the model handles several together), reducing unnecessary model calls or changing model size provides the best result. Once there are several replicas, our article on AI inference load balancing explains how routing can take cached work and busy compute into account.
Follow the complete request. A distributed trace records where a request traveled and how much time its stages consumed. OpenTelemetry, which graduated as a CNCF project on May 21, 2026, provides vendor-neutral observability tools. Its GenAI semantic conventions, the agreed field names for this kind of telemetry, continue to evolve for model invocations, token use and tool execution.
A token is a unit of text consumed or generated by a model. Token counts can help explain processing demand and cost. Tracing can distinguish time spent waiting from time spent generating an answer. Our article on owning the telemetry pipeline covers what OpenTelemetry standardizes and when running a collector is worth the extra layer.
Keep sensitive content out of unnecessary telemetry. Employee prompts, retrieved policy text and generated answers might contain private information. The OpenTelemetry GenAI attribute documentation identifies potential sensitive content. Engineers should capture latency and counts without indiscriminately storing full prompts, and enforce access controls, filtering and retention for any content they do need.
Test the service, not just the restart. If an inference node fails, Kubernetes may schedule a replacement Pod. That Pod still needs a suitable accelerator and model files. The application also needs its search and identity dependencies. A useful recovery test measures when employees can obtain a correct, authorized response again.
And if an AI agent can change records, the downstream application must authorize each action for the actual user: a model deciding to call a tool is not permission to perform the operation. Kubernetes security controls help protect workloads but do not replace business authorization.
These responses solve different problems. Scaling addresses constrained capacity. Tracing explains performance. Privacy controls protect the evidence. Recovery and authorization protect the service itself.
Whether to operate the model or buy inference
The team can keep hosting inference on Kubernetes or operate its application on Kubernetes while using a managed model API. Neither is the universal answer.
| Choice | Self-hosted inference | Managed model API |
|---|---|---|
| Hardware | Team manages accelerator capacity and utilization | Provider manages serving infrastructure |
| Scaling | Requires scheduling, model-serving metrics and spare capacity | Requires management of quotas, concurrency and provider limits |
| Control | More control over runtime and model deployment | Limited to provider-supported models and features |
| Economics | Hardware time, engineering, operations and storage | Usage charges, commitments and integration costs |
| Risk | Model loading, cluster and accelerator recovery | Network, service availability and data-processing arrangements |
For a company serving many models at sustained volume, managing inference may be worthwhile. A smaller team operating one assistant might avoid substantial GPU work by using a managed service. If it keeps inference in Kubernetes, dedicated GPU node pools (groups of GPU worker machines) or separate clusters may be appropriate where isolation, capacity or reliability justify them. A team that hosts a model itself must also choose an engine to serve it, and our guide to choosing an AI inference engine covers what to compare.
The company in our example can now compare options using measured request demand, service targets, operating effort and data requirements. That is more useful than deciding that every AI component must live in a Kubernetes cluster simply because the rest of the application does.
How deeply a team needs to go depends on its role. Most platform and application teams only need to recognize this pattern and measure where a request waits, which is enough to ask the right question early. Teams that host models themselves need more depth in accelerator scheduling and model serving, and the Kubernetes and KServe documentation linked below is written for them.
Kubernetes remains a strong foundation: it schedules services, helps maintain availability and gives teams familiar operational controls. AI adds resource constraints and application responsibilities that those controls cannot settle by themselves.
The important skill for platform teams is not treating AI as an entirely new world. It is knowing where familiar Kubernetes practices end, and where model-serving engineering must begin.
Go deeper
- CNCF Annual Cloud Native Survey 2025, CNCF, January 2026. Adoption figures, survey populations and limits.
- KubeCon North America 2026 AI Inference + Agentic track, CNCF, August 2026. The event’s emerging infrastructure priorities.
- Kubernetes GPU scheduling, Official device-plugin guidance.
- Kubernetes Dynamic Resource Allocation, Stable status, device claims and preemption limits.
- KServe generative-inference autoscaling, KServe. Model-serving scaling and KEDA metrics.
- OpenTelemetry graduation, May 21, 2026. Project milestone.
- OpenTelemetry GenAI semantic conventions, Evolving model, agent and tool telemetry.
- OpenTelemetry GenAI attributes, Privacy-sensitive instrumentation details.