

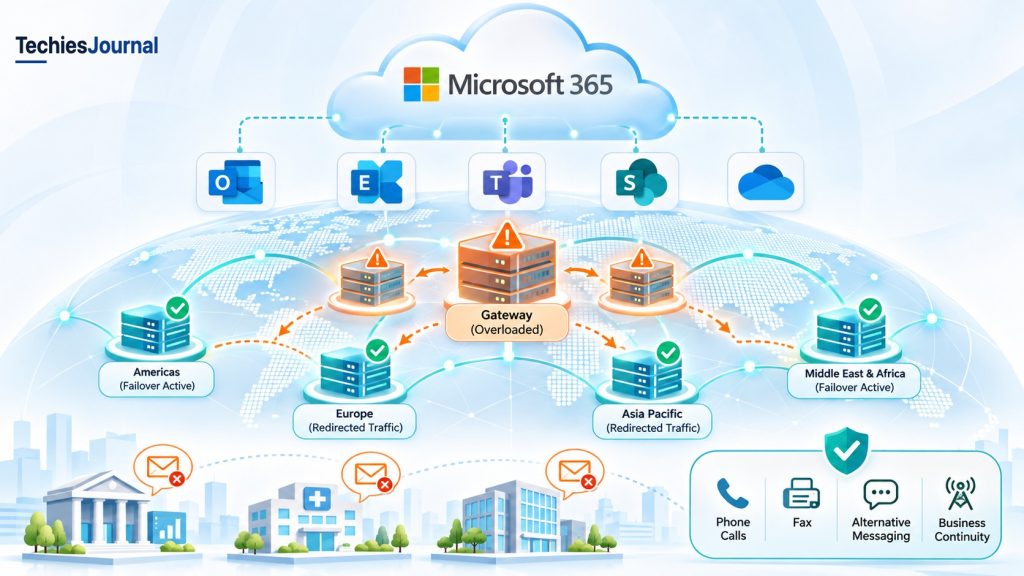
The November 2026 Microsoft 365 outage disrupted email worldwide for nearly 24 hours. Microsoft’s preliminary investigation explains how an older software defect, a change in traffic and reduced server capacity combined to cause widespread failures.
On Thursday, November 12, employees at businesses around the world began having trouble using Microsoft Outlook. Many could not access email, and some messages were delayed. The problem also affected features in other Microsoft 365 services that depend on Exchange Online, Microsoft’s cloud email platform.
For some organizations, this was more than an inconvenience. Financial firms used telephone and fax to confirm transactions. Companies arranging financial announcements turned to alternative ways to exchange information. Microsoft’s preliminary investigation later traced the incident to a software problem that had been present for months, but had not appeared under earlier operating conditions.
Here is what the records establish and what Microsoft had not yet fully explained as of November 21.
1. What happened?
The failure occurred in Microsoft’s cloud infrastructure rather than in individual Outlook installations. Outlook and other email applications connect to Exchange Online through systems that receive and direct their requests. During the outage, servers handling those connections became overloaded and stopped responding.
Microsoft said most people trying to use Exchange Online-dependent features were affected, although the experience differed by region, access method and time. Some users could not open their mailboxes. Others had intermittent access or delays in sending and receiving messages.
Microsoft also listed Teams, Copilot, SharePoint, OneDrive, Defender and several other services among those affected. This does not mean that every listed application stopped working. Microsoft said many of these services remained largely available but experienced problems with features connected to Exchange Online. Teams chats and meetings, for example, continued working for most of the disruption after they were moved away from the affected gateway.
Source: Microsoft preliminary PIR, pp. 2 to 4. The link is a copy of the report hosted by a third party.
2. How long did the outage last?
Microsoft recorded the main customer-impact period from 16:20 UTC on November 12 to 16:10 UTC on November 13, 2026: 23 hours and 50 minutes. In Eastern Standard Time, this was 11:20 a.m. Thursday through 11:10 a.m. Friday.
That duration describes the principal period of active impact. It does not mean every service was unavailable throughout those hours. Some applications recovered earlier, and Microsoft continued checking service health and processing delayed email after the main impact had ended. Its final customer updates were issued on November 14.
| Time (UTC) | Documented milestone |
|---|---|
| Nov 12, 01:07 | Teams traffic automatically moved onto the gateway also serving Exchange Online. |
| Nov 12, 16:03 | Microsoft’s monitoring detected growing connection problems. |
| Nov 12, 16:20 | Microsoft recorded the start of major customer impact. |
| Nov 13, 07:20 | Engineers began applying a change to undo the defective behavior. |
| Nov 13, 14:17 | Global webmail availability returned to expected levels. |
| Nov 13, 16:10 | Microsoft recorded the end of active customer impact. |
| Nov 14, 04:15 | Microsoft issued final customer updates after extended monitoring. |
Source: Microsoft preliminary PIR, pp. 2 and 4 to 6.
3. Who was affected?
Microsoft described this as a global incident. The biggest impact was on Exchange Online mailbox access and email delivery. Some features in other Microsoft 365 services were affected because they relied on the same email infrastructure.
The severity was uneven. A company might have been unable to use Outlook reliably while Teams meetings still worked. A different company could have faced disruption to a workflow that sent notifications through email. These distinctions matter: “Microsoft 365 outage” does not mean every customer lost access to every Microsoft 365 service.
Microsoft’s preliminary report did not provide a verified global count of affected users or organizations. Public outage-reporting websites recorded complaints, but those counts should not be treated as the number of unique customers affected.
Source: Microsoft preliminary PIR, p. 2.
4. What was the business impact?
Reuters documented businesses using alternative communication methods while email was disrupted. In Taiwan, some financial firms had trouble with fund-management activities, and one firm used fax to confirm transactions. British banks HSBC and Barclays activated incident-response arrangements, while reporting that many customer-facing services continued normally.
The interruption also affected the communication around financial results. Reuters reported that insurer Aviva shared alternative telephone numbers and transferred recordings by Bluetooth. Exchange operator Euronext directed listed companies toward telephone contact for urgent communications. Other organizations also relied on telephone calls while email was unreliable.
These examples show operational disruption, but they do not establish a total financial cost. There is no verified worldwide loss figure in the sources reviewed for this article. We should not calculate one from user complaints, anecdotal accounts or unverified estimates.
Source: Reuters, November 13, 2026.
5. What caused the outage?
Microsoft’s preliminary investigation identified three conditions that combined to bring down the gateway that handled connections to several Microsoft 365 services.
The first was an older software defect. In July, Microsoft had started deploying a change specifically for its Microsoft 365 gateway servers. It passed the company’s normal deployment process and operated for more than three months without visible problems. Under certain traffic conditions, however, the change made internal server operations interfere with each other. Processing power and memory could become exhausted until a server stopped responding. Microsoft called this a lock contention problem.
Microsoft said its testing had missed the defect because the computers and traffic patterns used in testing differed from production. The problem became worse on newer computers with more processor cores, while its load tests often used weaker machines. The company emphasized that this was a gateway-specific change, not a defect affecting ordinary Windows installations.
The second condition was a change in traffic. About 15 hours before the incident, Teams automatically moved traffic from an alternative gateway onto the primary gateway that also served Exchange Online. Such switching is normally part of keeping services available, but it placed additional work onto the affected infrastructure and changed the mix of requests it received.
The third condition was reduced capacity. Almost 14% of that gateway’s server capacity was unavailable because of a separate issue from the previous day. Microsoft said the remaining capacity should have been sufficient under normal conditions. But alongside the traffic change, the reduced capacity helped expose the older defect during a busy period in the United States.
When servers failed, Microsoft’s system redirected their traffic to servers that still appeared healthy. Those servers had the same hidden defect. As more work reached them, they failed as well. Microsoft reported that more than 80% of gateway servers were unresponsive at the worst point.
Microsoft had designed boundaries intended to stop a failure in one part of the infrastructure from spreading across regions. It said a separate issue prevented these boundaries, called bulkheads, from containing the failure. The preliminary report did not fully explain that additional problem.
Source: Microsoft preliminary PIR, pp. 3 to 4.
6. Why did recovery take so long?
Microsoft first tried to repair and restart affected servers and shift connections to other infrastructure. Some servers appeared healthy when they restarted but stopped responding again as waiting traffic returned. The scale of the failure was larger than the condition its normal automated recovery systems were designed to handle.
Undoing the software change was also difficult. The defect had been present since July, so the usual tools for quickly rolling back a recent deployment could not simply reverse it. Engineers developed a new update that restored the affected connection-handling code to an earlier working state.
The company then applied that change to groups of servers and carefully returned them to service. Recovery became sustained on November 13, with webmail recovering before all other access methods. Microsoft continued monitoring and clearing delayed mail after active impact ended.
Source: Microsoft preliminary PIR, pp. 4 to 6.
7. What did Microsoft acknowledge?
Microsoft’s report acknowledged that its testing did not recreate the combination of hardware and traffic conditions that exposed the software defect. It also acknowledged that its normal regional protections failed to stop the incident spreading and that its automated recovery process was not designed for a failure this broad.
The Associated Press reported that Microsoft’s earlier public update described the incident as introduced by an issue during an earlier network capacity upgrade that surfaced after a recent network change. The preliminary report gives the fuller account described above, and the sources reviewed do not explain how the two descriptions relate.
Microsoft CEO Satya Nadella subsequently commented on the outage and the need to catch such defects in testing. He also discussed the wider challenge of software stability when AI helps developers find bugs and produce patches more quickly. Those remarks do not establish that AI caused this incident. Microsoft stated that the outage was a technical issue unrelated to cyberattacks or AI agents, and the preliminary root-cause report does not identify AI-generated code as a cause.
Sources: Microsoft preliminary PIR, Mint reporting on Nadella, November 19, 2026 and Associated Press on Microsoft’s statement.
8. What did Microsoft fix, and what remains unknown?
Microsoft reported completing several immediate measures. These included restoring the earlier working connection-handling behavior, adding capacity, extending the email delivery window for delayed messages, improving monitoring and adding controls to reduce the risk of traffic being redirected in a way that causes another cascade.
These are Microsoft-reported actions, not independent proof that every longer-term weakness has been removed. As of this article’s November 21 evidence cutoff, the preliminary report had not fully explained why regional containment failed, what caused the separate 14% capacity reduction or how all permanent improvements would be verified. Microsoft’s final post-incident report was not publicly available when this article was reviewed.
The outage also illustrates why companies need to know which essential activities depend on cloud communication tools and how they will communicate when those tools cannot be reached. TechiesJournal explores that broader business-continuity question in The Cloud Dependency Paradox: When Reliable Technology Doesn’t Guarantee Business Continuity. The present report focuses on the documented Outlook incident rather than repeating that analysis.
The incident has been resolved. Microsoft’s preliminary investigation explains how the main failures developed, while the final report remains the next source for assessing its longer-term corrective actions.
References and further reading
- Preliminary Post-Incident Report for Microsoft 365 (Microsoft, November 15, 2026): Microsoft-authored cause, chronology and immediate measures. Preliminary and subject to change. The link is a copy of the report hosted by a third party.
- Faxes, phones and Bluetooth: Microsoft outage forces businesses to find fixes (Reuters, November 13, 2026): independently reported company examples and alternative communications.
- Microsoft says services fully restored after global outage (Associated Press, November 14, 2026): independent coverage of restoration and Microsoft’s exclusion of cyberattack and AI-agent causes.
- Nadella discusses Outlook outage and software stability (Mint, November 19, 2026): interview reporting. Distinguish commentary on broader AI patch velocity from this incident’s documented cause.
Source review: November 21, 2026. This article is based on Microsoft’s preliminary report. A final report was not publicly available at the time of review.