

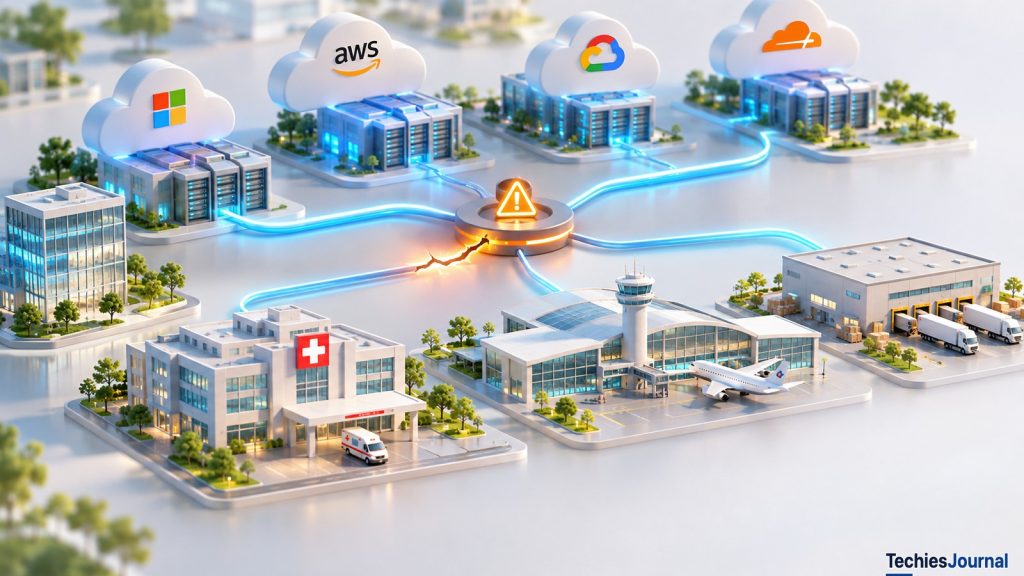
What five years of major technology disruptions reveal about shared dependencies, business impact, and resilience decisions.
A business can be disrupted even when its own systems are healthy
An organization has two network connections, clustered servers, replicated databases, backups, and a disaster recovery site. Its engineers have spent years removing known internal failure points. Then employees lose access to an essential external service. The organization’s own equipment is functioning, yet an important business process cannot continue normally.
This is not proof that cloud computing has weakened reliability. In many cases, cloud platforms provide stronger availability, security, and operational capability than an organization could economically build itself. But moving systems to an external provider changes which failures a company can prevent, which it can recover from directly, and which it must endure while someone else restores service.
The distinction matters because a business process rarely depends on one application alone. A customer order may need an identity service, a payment intermediary, a network security platform, and a data system. Any one can become a constraint even if the rest are operational.
The question is not whether businesses should avoid cloud and software-as-a-service providers. It is whether their continuity plans account for the full chain of technology and organizations required to deliver essential services.
Five years of significant disruptions
The incidents below were selected for their documented consequences and different failure mechanisms. This is an illustrative register, not a census of worldwide outages. Durations and impacts refer to different measures and must not be compared as though they were the same statistic.
| Date | Incident | Documented operational or financial impact | What the case illustrates |
|---|---|---|---|
| April 2022 | Atlassian Cloud | 883 sites representing 775 customers deleted, with some restoration extending up to 14 days | Recovery at scale can differ from ordinary failover Atlassian review |
| February 2024 | Change Healthcare | UnitedHealth reported $2.2 billion in 2024 direct response costs and $867 million in Optum Insight business disruption impacts | Critical transaction intermediaries connect many otherwise separate organizations UnitedHealth 2024 Form 10-K |
| July 2024 | CrowdStrike software update | Delta reported about 7,000 cancelled flights, a $380 million revenue impact, and $170 million in additional expenses | Common software components can create prolonged operational recovery Delta 2024 Form 10-K |
| June 2025 | Google Cloud | Broad service disruption originating in shared API-management infrastructure | Global policy and control dependencies can affect many services Google Cloud incident report |
| June 2025 | Cloudflare | Cloudflare reports 2 hours and 28 minutes of disruption affecting several products | One platform can depend on another provider’s storage service Cloudflare June 2025 postmortem |
| October 2025 | AWS us-east-1 | DynamoDB-related DNS problems were followed by EC2 and load-balancer recovery difficulties | Resolving the initial fault does not restore all dependent services immediately AWS incident report |
| November 2025 | Cloudflare | Widespread disruption caused by propagated configuration data | Common configuration paths can create shared exposure Cloudflare November 2025 postmortem |
| February 2026 | Google Vertex AI Gemini API | Increased API errors for approximately 1 hour and 58 minutes | AI-backed applications can share conventional platform dependencies Google Cloud status report |
| November 2026 | Microsoft Exchange Online | Mailbox connectivity and certain dependent Microsoft 365 features were affected on November 12 to 13. Microsoft’s preliminary root cause was an earlier network capacity upgrade. Consolidated financial losses were not verified | SaaS features may share underlying services even when product names differ PennO365 extract of Microsoft incident reports |
The table alone cannot establish that outages are becoming more frequent. Uptime Institute’s 2025 research, in fact, reported a fourth consecutive year of declining overall outage frequency and general reported severity. It also cautioned that outage data should be treated skeptically because of limited transparency and reliable reporting. Uptime Institute analysis
A more productive comparison asks how a disruption moved from a technical component into a business process, and what recovery remained possible for the people depending on it.
The difference between having backups and getting work back: Atlassian
In April 2022, an Atlassian maintenance script deleted entire cloud sites instead of only the intended application information. Atlassian’s post-incident review records 883 sites and 775 affected customers, with the final restorations completed on April 18. Some customers experienced disruption lasting up to 14 days. Atlassian review
Atlassian had recovery mechanisms, but its established restoration process was suited to individual sites or smaller groups. Rebuilding hundreds of sites across connected products required additional procedures and automation. The company’s review also describes how deleting site records disrupted contact and support workflows used to communicate with customers.
The meaningful distinction is between three questions: Can infrastructure survive a component failure? Is data protected? Can a complete business service be restored at the required scale and speed? A positive answer to one does not guarantee the others.
For a customer, this suggests a proportionate continuity test. Identify which work would stop if the SaaS product were unavailable for a day or a week. Determine whether essential documents, contact details, approvals, or work instructions are accessible by an approved independent method. A full duplicate SaaS platform may not be necessary. A tested way to carry on the most important work may be more useful.
The shared transaction service: Change Healthcare
The February 2024 cyberattack on Change Healthcare disrupted healthcare transaction services. UnitedHealth isolated affected systems to contain the threat, which contributed to interrupted claims and payment-related workflows for organizations relying on the platform. This was a cybersecurity incident, not an ordinary cloud infrastructure outage. UnitedHealth 2024 Form 10-K
In its 2024 annual filing, UnitedHealth reported $2.2 billion of direct response costs and an estimated $867 million of business disruption impacts in Optum Insight. It also reported providing more than $9 billion in interest-free loans to care providers through the end of 2024. The filing says the $2.2 billion of direct response costs includes costs associated with providing those loans. The loans themselves represent financing support and must not be added to the incident’s losses. The filing’s financial categories should also not be turned into a single industry-wide loss estimate. UnitedHealth 2024 Form 10-K
The incident demonstrates how one intermediary can be essential to transactions between many otherwise independent organizations. Their own servers and networks might remain available, yet claims and payments can still be interrupted because a necessary external step cannot be completed.
The practical issue is not whether every healthcare provider should maintain its own transaction network. It is whether critical business processes have been mapped through the external intermediary, whether alternative arrangements are contractually and technically feasible, and whether cash-flow or manual-process contingencies are adequate for a prolonged interruption.
When computers return but operations do not: CrowdStrike and Delta
On July 19, 2024, a faulty CrowdStrike security content update led to widespread failures on Windows systems. The underlying problem was a common software component, not a universal outage of a cloud region. Delta 2024 Form 10-K
Delta Air Lines disclosed approximately 7,000 flight cancellations over five days, an estimated $380 million direct revenue impact, and approximately $170 million in additional operating expenses. It also identified approximately $50 million in fuel expenses avoided because of cancelled flights. These are distinct company-reported financial effects, not a confirmed net-loss calculation for the entire incident. Delta 2024 Form 10-K
An airline must coordinate aircraft, crews, passengers, airports, and schedules. Restoring a computer does not instantly return all those elements to their proper operational state. Delays create backlogs, and backlogs create additional recovery work.
That difference applies beyond airlines. A recovered order system may still contain transactions that need reconciliation. A restored customer service platform may face an accumulated queue. A hospital system may need to reschedule care. An enterprise should therefore measure not only the time until its technology returns, but also the time until the business can again deliver an acceptable service.
A dependency behind the provider: Google Cloud and Cloudflare
On June 12, 2025, a change to globally distributed policy information interacted with a software defect in Google Cloud’s API-management infrastructure. Multiple Google services experienced disruption. Google’s incident report says the new code path lacked error handling and feature-flag protection, so blank policy fields that replicated globally within seconds caused the policy-checking service to crash repeatedly in every region. A kill switch ended the main impact in about 40 minutes, while recovery in us-central1 took up to about 2 hours and 40 minutes. Google Cloud incident report
The same day, Cloudflare reported two hours and 28 minutes of impact across services including Workers KV, Access, Gateway, WARP, and Turnstile. Its own timeline spans a little longer, about two hours and 36 minutes. Cloudflare identified the failure of an external storage dependency used by Workers KV as the proximate trigger. A range of Cloudflare products relied on that service for configuration, authentication, or content delivery. The company reported that important unaffected services remained operational, including core DNS and much of its CDN functionality. Cloudflare June 2025 postmortem
Here a business could depend on Cloudflare while Cloudflare itself depended on another infrastructure service. The business may have no direct relationship with that underlying provider. Counting direct vendors, or operating applications on different platforms, does not necessarily establish independent failure paths.
The lesson is to trace dependencies at the level that matters for a critical business function. It is also important not to assume that every feature of a provider failed. Precisely identifying which services were affected is part of an honest resilience assessment.
Why one restored component did not finish AWS recovery
In October 2025, a DNS-management issue involving Amazon DynamoDB in the us-east-1 region affected connections to a regional endpoint. AWS’s post-event report describes subsequent problems with EC2 instance launches, host management, and Network Load Balancer health checks. AWS incident report
The initial DynamoDB issue was resolved before all dependent operations had recovered. Some existing EC2 instances remained healthy while launching new instances was impaired. This distinction changes what customers actually experience. A workload that runs on sufficient existing capacity may continue operating while one that needs new instances, replacement capacity, or particular management operations struggles.
The relevant engineering concern is not simply whether multiple availability zones exist. It is whether a proposed recovery action depends on a shared service that might also be impaired. For example, a failover plan that requires new capacity must be tested against capacity and control-service constraints rather than assuming that provisioning always succeeds.
TechiesJournal’s Cloud Control Plane Outages: Why Running Servers Do Not Mean a Working Service covers how those control services fail. They matter here only because they help explain the gap between a provider recovering its infrastructure and a customer restoring its business function.
What the recent Microsoft 365 incident adds
On November 12, 2026, Microsoft reported Exchange Online mailbox connectivity problems that could affect Outlook on the web and several connection protocols. Updates during the incident described a large number of servers becoming unexpectedly unavailable, which shifted load onto the remaining infrastructure, and a core process on the affected servers becoming overwhelmed. Later updates described improving stability after Microsoft applied a patch to an upstream authentication and routing configuration component. PennO365 extract of Microsoft incident reports
By November 14, the records Microsoft had sent to the University of Pennsylvania’s PennO365 service showed both incidents as service restored. Microsoft gave a preliminary root cause: an issue introduced during an earlier network capacity upgrade that surfaced after a recent network change. It said this was a technical issue not related to cyber or AI, and that a full Post-Incident Report would follow.
Microsoft also reported effects on particular functionality in other Microsoft 365 products that relied on Exchange Online. This does not mean every connected product or every feature was unavailable.
Evidence boundary, reviewed November 14, 2026: Microsoft’s formal root-cause field was still empty and its full Post-Incident Report had not been published in the records reviewed, so the preliminary cause may change. The two incident records also give different end times. Consolidated business financial losses were not verified. Accordingly, this incident is a recent illustration of SaaS functional dependencies, not a basis for a financial loss claim or a definitive attribution of cause.
The risk sits in the business process, not just the application
Taken together, these cases show four different ways essential work can stop. Data may be difficult to restore at scale. A transaction intermediary can be unavailable. Shared software can interrupt many organizations at once. A service that appears independent may rely on another provider or a common control component.
The useful unit of analysis is an important business service. Imagine a company accepting an online payment. Its storefront may remain healthy while the payment intermediary is unavailable. Alternatively, its storefront may be offline while an approved telephone or manual process preserves a limited amount of essential business. In both situations, an application uptime percentage alone is an incomplete measure of the customer’s experience.
Accessible text alternative for this figure
The service is a chain of five links: storefront, identity service, payment intermediary, security platform and data system.
Four links are working. The payment intermediary is down.
With no plan, the customer cannot pay and the business service stops.
With a tested fallback, an approved phone or manual process bypasses the broken link, and essential payments continue in a limited way.
This is not a new discovery. Established contingency and operational-resilience practices already distinguish technical recovery from the continuation of critical business functions. NIST’s contingency-planning guidance and financial-sector operational-resilience frameworks emphasize business impact, dependencies, recovery priorities, and testing. NIST contingency-planning guidance Bank of England resilience guidance
The change for a modern enterprise is to apply those questions to external and downstream services it does not operate directly.
What do the losses actually tell us?
Delta and UnitedHealth disclose material impacts, but they describe different cost categories and very different business environments. Adding those figures together would create an impressive number without a useful interpretation.
Uptime Institute offers broader context. In its 2025 annual outage analysis, 54% of respondents to its 2024 survey said their most recent significant-to-severe outage cost more than $100,000, and one in five (20%) reported more than $1 million. These are survey responses about selected impactful outages, not the share of all cloud outages exceeding those amounts. The report also cautions that outage measurement is incomplete. Uptime Institute analysis
A company’s own decision should instead start with the likely consequence of losing one business service for an hour, a day, or several days. It should consider interrupted transactions, staff productivity, customer harm, regulatory obligations, cash flow, recovery expenses, and the backlog after service restoration. Where the company lacks defensible estimates, it should label them as scenarios rather than published loss statistics.
What should an enterprise do differently?
A sound response does not require duplicating every technology platform. It requires matching protection to the interruption the business cannot tolerate.
First, name the essential business service, not only the application. Then trace the systems, external providers, identity services, data sources, and transaction intermediaries needed to deliver it. Record which of those dependencies are shared across apparently independent operations.
Next, define an acceptable interruption and a minimum service level. An internal knowledge site may tolerate a day of disruption while a payment or emergency communication function cannot. The answer should reflect the business consequence, not the prestige of the technology.
Finally, rehearse a specific failure. Can staff reach an independent emergency contact list if the usual identity or collaboration platform is unavailable? Can incoming transactions be safely queued and reconciled? Can critical information be recovered without the normal SaaS interface? Does failover require a control service that could also be down? The exercise should measure real restoration of the business function, including backlogs and manual work.
There are trade-offs. Independent platforms, multiple regions, and multi-cloud architectures may reduce certain correlated failures, but they also add operating cost, replication complexity, and security responsibilities. Sometimes a tested alternative business process is a more proportionate control. Sometimes the cost and consequences justify substantial technical redundancy. The choice should follow the business requirement and a realistic test.
A limited role for AI
AI-based operational tools can assist with log analysis, alert grouping, and investigation suggestions. Their advertised capabilities are not, by themselves, evidence that they shorten recovery during major incidents. Any production-changing action still needs appropriate verification and authority.
AI services can also become dependencies. Cloudflare reported that Workers AI inference requests failed during its June 2025 Workers KV incident. This is a concrete example of a modern AI feature depending on conventional configuration and platform infrastructure. Cloudflare June 2025 postmortem
AI therefore belongs in the same dependency and continuity assessment as other critical services. It may improve the team’s ability to investigate an incident, but it does not remove the need for independent communications, recovery tests, and sound operating controls.
Reliability and resilience should be measured together
Cloud services have made substantial reliability and recovery capabilities available to more organizations. The incidents in this review do not prove that outsourcing infrastructure makes a business less reliable, and they do not establish that operating multiple providers is always better.
They do show why platform uptime and business continuity are different outcomes. A service can be designed with redundancy and still suffer a shared configuration failure. A provider may restore its technical systems while its customers are still recovering business processes. An organization may avoid the original fault yet experience consequences because an essential intermediary is unavailable.
A useful resilience plan therefore starts with the business service that must continue, follows its dependencies beyond the organization’s own network, and tests what can actually operate during an interruption. It spends on independence where the business impact warrants the cost, rather than trying to eliminate every dependency.
Reliable technology helps keep a business running. Business resilience also requires a plan for when that technology is unavailable.
References and further reading
- Atlassian: Post-Incident Review on the April 2022 Outage. Customer counts, deletion mechanism, support impact and recovery timeline.
- UnitedHealth Group: 2024 Form 10-K. Discussion of Change Healthcare incident costs and business disruption.
- Delta Air Lines: 2024 Form 10-K. Discussion of July 2024 operational and financial impacts.
- Google Cloud: June 12, 2025 Service Disruption Incident Report. Mechanism and recovery.
- Cloudflare: Cloudflare Service Outage June 12, 2025. Shared storage dependency, affected and unaffected products.
- AWS: Summary of the Amazon DynamoDB Service Disruption in the Northern Virginia Region, October 2025. Sequence of the DynamoDB, EC2 and load-balancer problems.
- Cloudflare: November 18, 2025 Outage. Configuration propagation and service effects.
- Google Cloud: Vertex AI Gemini API Incident, February 27, 2026. Official Google Cloud incident record.
- Microsoft: Exchange Online incident EX1550543 and Microsoft 365 incident MO1550821, November 12 to 14, 2026. Microsoft’s incident reports as copied in the University of Pennsylvania PennO365 incident extract, which refreshes every 15 minutes, so the page changes as Microsoft updates its reports.
- Uptime Institute: Annual Outage Analysis 2025. Executive summary: outage trends, reported costs and measurement limitations.
- TechiesJournal: Cloud Control Plane Outages: Why Running Servers Do Not Mean a Working Service. How cloud control services fail and what to check.
- NIST: SP 800-34 Rev. 1, Contingency Planning Guide for Federal Information Systems. Business impact analysis, interdependencies, recovery priorities and testing.
- Bank of England and PRA: SS1/21, Operational resilience: Impact tolerances for important business services. Important business services, impact tolerances, mapping and scenario testing.
Sources were read on November 14, 2026. The Microsoft incident was still being reviewed, and incident details can change.