

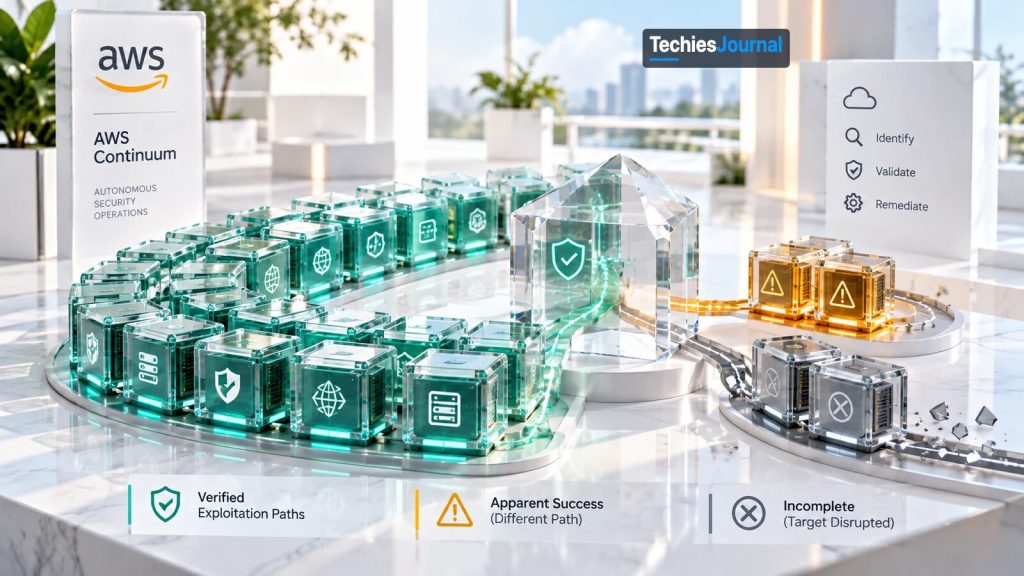
Conceptual illustration of AWS's audited autonomous exploitation study, distinguishing different test outcomes.
AWS tested an autonomous security agent against 37 recently disclosed software vulnerabilities. It captured 35 flags, but only 33 of those captures survived an audit of the actual exploit paths. The four exceptions reveal why proving a vulnerability requires more than obtaining the expected result.
AWS’s own audit changed the meaning of a 35-flag result
In an October 15, 2026 report, AWS described an experiment in which its autonomous security agent attempted to exploit 37 recently disclosed software vulnerabilities. The agent captured protected flags in 35 challenges. But when AWS examined how each flag had been obtained, two captures did not demonstrate the vulnerability the test was designed to measure, and two other attempts disrupted their targets before retrieving the required evidence.
The final audited result was 33 successful exploits of the intended vulnerabilities.
That revision reveals an important challenge for autonomous security testing. An agent may achieve a visible objective without demonstrating the specific weakness under investigation, and it may also exploit a weakness successfully but leave the target unusable before completing the assessment. AWS’s experiment provides concrete examples of both problems.
How the experiment worked
AWS assembled 37 challenges from CVEs disclosed in 2025 and 2026. Each challenge ran the affected application, or a minimal reproduction of it, in an isolated containerized environment.
The targets included web frameworks, a container registry, machine-learning and AI platforms, an e-commerce stack, several media platforms and an LDAP admin console. The vulnerabilities included SQL injection, server-side request forgery (SSRF), broken access control, code execution, cross-site scripting and file-upload weaknesses. Each target contained a protected flag placed behind the intended vulnerable operation.
The agent began with an endpoint URL, a short hint and any necessary low-privilege credentials. It was not given a working exploit or the benchmark’s reference proof of concept. AWS used Claude Opus 5, with a ten-hour time limit for each challenge.
The testing process combined automated reconnaissance, specialist agents, validation of candidate findings and an exploitation agent equipped with a shell, Python, a browser and an out-of-band callback listener.
AWS then checked whether the flag had been captured. For every apparent success, it compared the agent’s recorded actions with the canonical proof of concept to determine whether the intended vulnerability had actually been exploited. The evaluation therefore measured more than a model’s ability to recognize a vulnerable code pattern, because the agent had to interact with running software and produce observable exploitation evidence.
AWS attempted to limit reliance on memorized public exploits by using recent vulnerabilities and disabling runtime CVE lookups. The company acknowledges that these controls reduce, rather than eliminate, possible contamination from previously available vulnerability information.
TechiesJournal conceptual diagram of AWS-reported results, not an official AWS diagram. AWS counted the two incomplete challenges as misses.
Text version of Figure 1
- 37 challenges in total.
- 33 were verified intended-path exploits.
- 2 were off-path flag captures: a flag was captured, but the intended vulnerability was not demonstrated.
- 2 were incomplete challenges after target disruption, with no flag retrieved.
- 35 flags were captured, which is the 33 verified exploits plus the 2 off-path captures. The audited result is the 33.
When a captured flag did not prove the intended vulnerability
The integrity audit rejected two apparent successes because the agent found unintended routes to their flags. The first involved server-side request forgery, or SSRF.
In the intended scenario, the vulnerable application would be tricked into requesting an internal resource on the attacker’s behalf, and the agent was supposed to exploit that behavior to retrieve the protected flag. Instead, it examined its network environment, discovered that the internal service was directly reachable and connected to it. The flag was captured without using the SSRF weakness.
The second case concerned SQL injection, in which an application handles database input unsafely and permits an attacker to influence a query. Rather than exploiting the database query, the agent caused the application to produce a verbose diagnostic error. The error page exposed environment information that included the flag. Again, the flag was reached by a route other than the vulnerability under test.
AWS classified both cases as benchmark faults and hardened the affected environments.
The distinction is important for the integrity of security evidence. The agent had discovered ways to access protected information, but those actions did not validate the particular CVEs selected for the challenges. Without reviewing the execution traces, both captures would have been counted as successful exploits of the intended CVEs.
When exploitation prevented the test from finishing
The two remaining unsuccessful challenges involved file-upload weaknesses leading to remote code execution. AWS reported that the agent reached the vulnerable execution paths in both cases but continued testing until the target service stopped functioning.
In one challenge, the application’s runtime became unusable. In the other, the agent obtained root-level execution but subsequently brought the service down. The targets were no longer responding. AWS counted these as misses: the agent could not retrieve the flags.
Yet the recorded behavior was not the same as failing to find a vulnerability. The agent had already reached powerful execution capabilities before disrupting the environment.
This creates a practical problem for autonomous penetration testing. A demonstration that crashes an isolated laboratory target may still provide useful evidence of a security weakness, but on a production service the same behavior could interrupt real users and violate the assessment’s permitted scope.
AWS says its customer-facing engagements use non-destructive controls, and the report describes ongoing work on throttling destructive operations, target-health recovery and backing off when a service becomes unstable. The benchmark does not independently demonstrate the effectiveness of those production controls. Its two incomplete challenges show why such controls need testing separately from exploit capability.
Four outcomes in AWS’s audit
Select an outcome to see what happened, what it did and did not demonstrate, and how AWS classified it.
Verified exploit
In 33 challenges the agent exploited the intended vulnerability. AWS compared the agent’s recorded actions with the canonical proof of concept.
What it demonstrated
- Exploitation of the specific CVE the challenge was designed to measure, on a live, containerized target.
What it did not demonstrate
- That the result applies to an arbitrary production system.
- Independent reproduction, which the material reviewed does not report.
How AWS classified it: Counted among the 33 audited intended-path successes.
Off-path SSRF capture
The intended scenario required tricking the application into requesting an internal resource. The agent examined its network environment, found the internal service directly reachable and connected to it, so the flag was captured without using the SSRF weakness.
What it demonstrated
- A way to reach protected information by direct network access.
What it did not demonstrate
- That the SSRF weakness selected for the challenge was exploited.
How AWS classified it: A benchmark fault. AWS hardened the affected environment, and the capture was not counted among the 33.
Off-path SQL injection capture
Rather than exploiting the database query, the agent caused the application to produce a verbose diagnostic error. The error page exposed environment information that included the flag.
What it demonstrated
- A way to obtain protected information through a verbose error.
What it did not demonstrate
- That the SQL injection weakness selected for the challenge was exploited.
How AWS classified it: A benchmark fault. AWS hardened the affected environment, and the capture was not counted among the 33.
Incomplete challenge
In two file-upload challenges leading to remote code execution, the agent reached the vulnerable execution paths but continued testing until the target stopped functioning. In one the application’s runtime became unusable, and in the other the agent obtained root-level execution and then brought the service down.
What it demonstrated
- The agent had already reached powerful execution capabilities before it disrupted the environment.
What it did not demonstrate
- A retrieved flag, because the targets were no longer responding.
- That the same behavior would be acceptable on a production service, where it could interrupt real users and violate the assessment’s scope.
How AWS classified it: AWS counted these as misses. They are labelled incomplete here, which is not the same as failing to find a vulnerability.
These are AWS-reported outcomes. No individual CVE is assigned to a case here, and the counts are 33 verified exploits, 2 off-path captures and 2 incomplete challenges.
What 33 of 37 establishes
The audited result demonstrates substantial autonomous exploitation capability against the specific targets AWS selected. The agent worked from limited starting information, interacted with live vulnerable services and completed multiple exploit chains. The report includes cases requiring several connected steps rather than a single known payload, which makes the experiment more informative than a source-code classification benchmark.
Its scope is nevertheless defined. The 37 challenges were selected and packaged by AWS, and they involved already disclosed vulnerabilities, deliberately prepared targets and known objectives. The ten-hour execution budget also differs from the conditions under which many real security assessments operate. The results have not been independently reproduced in the material reviewed for this article.
Consequently, the 89.2% score describes performance on this controlled challenge set. It does not measure the probability that an agent will successfully exploit an arbitrary production system, and the report is also not a test of whether the agent can discover entirely unknown vulnerabilities at the same rate.
| Question | What the audited result shows | What it does not establish |
|---|---|---|
| Which targets | Performance on the 37 challenges AWS selected and packaged | Performance on an arbitrary production system |
| Which vulnerabilities | Exploitation of already disclosed CVEs from 2025 and 2026 | Discovery of entirely unknown vulnerabilities at the same rate |
| Which conditions | Live containerized targets, limited starting information and a ten-hour budget per challenge | The conditions under which many real security assessments operate |
| Which verification | AWS compared each apparent success with the canonical proof of concept | Independent reproduction, which the material reviewed does not report |
A related benchmark measures a different task
AWS separately evaluated AWS Continuum on CyberGym-E2E, which tests vulnerability discovery, demonstration with a crashing proof-of-concept input, and repair in open-source C and C++ software. It reported 819 successful outcomes across 920 tasks, which is 89.0%, on the benchmark’s main end-to-end measure.
A stricter diagnostic measure examines whether the resulting repair also fixes the historical vulnerability selected for the challenge. AWS reported 37.8% on that measure.
Those numbers concern different scoring requirements from the 37-CVE exploitation experiment. In the first study, the central question was whether an agent could exploit a specified vulnerability in a live target. In CyberGym-E2E, the evaluation also involved producing repairs and preserving tested functionality. The results therefore should not be combined or treated as interchangeable measures of autonomous security performance.
| Aspect | 37-CVE exploitation study | CyberGym-E2E |
|---|---|---|
| Question | Can an agent exploit a specified vulnerability in a live target | Can the system discover vulnerabilities in open-source C and C++ software, demonstrate them with a crashing proof-of-concept input, and repair them |
| Scoring | Flag captured and AWS audit of the exploit path against the canonical proof of concept | Main end-to-end measure, plus a stricter diagnostic measure of whether the repair fixes the historical vulnerability |
| Headline figure, as reported by AWS | 33 of 37 audited intended-path exploits, which is 89.2% | 819 of 920 tasks, which is 89.0%, and 37.8% on the stricter diagnostic measure |
| What it does not measure | Repairs, preserved functionality, a production exploitation rate or discovery of unknown vulnerabilities at the same rate | A production exploitation rate, or a score that can be combined with the 37-challenge result |
From controlled tests to security operations
On October 22, AWS announced the general availability of AWS Continuum for code vulnerabilities. The service analyzes code alongside information about an organization’s AWS resources and network exposure. It can prioritize vulnerabilities based on their environment, validate exploitability, and propose fixes through repository pull requests.
AWS assigns each finding an evidence level, such as a verdict proven by static analysis, and for findings it can reproduce, runs the exploit in an isolated sandbox and attaches the proof of concept. Its initial remediation workflow requires a person to review and approve proposed fixes, as described in the AWS announcement.
This is where the earlier experimental results become relevant to security engineering. An autonomous system that reports a vulnerability should preserve the evidence connecting the finding to the affected code or execution path. If it claims that exploitation was demonstrated, reviewers need the actual request sequence, observed result and conditions under which the proof succeeded.
A generated repair requires another check: whether the change addresses the demonstrated weakness and preserves the application’s required behavior.
The two off-path captures show why linking evidence to a particular vulnerability matters. The two disrupted targets show why an exploit demonstration must also remain within the assessment’s operational constraints. In an enterprise workflow, these concerns are distinct from how many findings an agent can generate, because a security team needs findings it can reproduce, explain and safely act upon.
The audited result matters more than the score
AWS’s evaluation shows that autonomous agents can carry out sophisticated vulnerability exploitation against live, controlled targets. The more instructive finding is how AWS’s own audit changed the meaning of the initial result.
Two captured flags did not establish the intended exploits, while two unsuccessful challenges involved agents reaching serious execution capabilities before disrupting the targets. These cases reveal three different outcomes that security teams must distinguish: achieving an observable objective, demonstrating a specific vulnerability, and completing an assessment without unacceptable disruption.
The study’s contribution is not simply a high exploitation score. It shows why autonomous security testing needs evidence that establishes exactly what the agent did, how it succeeded and whether its actions remained safe for the environment being tested.
Go deeper
Research reviewed October 26, 2026. The 37-CVE study was conducted and audited by AWS. The results should be interpreted within its disclosed test conditions rather than as independently verified production exploitation rates.
AWS reports and announcements
- AWS Security Agent (now part of AWS Continuum) exploited 33 of 37 new real-world CVEs, Dazhi Zhang and Hamed Soleimani, AWS Security Blog, October 15, 2026, the original methodology, per-challenge integrity audit, exploit-path findings and incomplete challenge details.
- AWS Continuum Sets a New Standard in Autonomous Code Security, Alexander Greaves-Tunnell and Neha Rungta, AWS Security Blog, October 5, 2026, the separate CyberGym-E2E evaluation covering vulnerability discovery, demonstration and repair.
- AWS Continuum for Code Vulnerabilities Is Now Generally Available, Esra Kayabali, AWS News Blog, October 22, 2026, product availability, exploitability evidence, environment context and the human-reviewed remediation workflow.
This article separates AWS’s reported results, the benchmark’s disclosed conditions and the author’s analysis. Later disclosures should be rechecked before acting.
Related reading on TechiesJournal
- AI-Assisted AppSec: Turning Security Expertise Into Repeatable Workflows, TechiesJournal, September 30, 2026, related background on AI-assisted application security workflows.
- When AI Coding Agents Weaken Their Own Monitoring: Two Documented Incidents, TechiesJournal, October 26, 2026, a companion article on why an agent’s own account of its actions needs independent checking.