

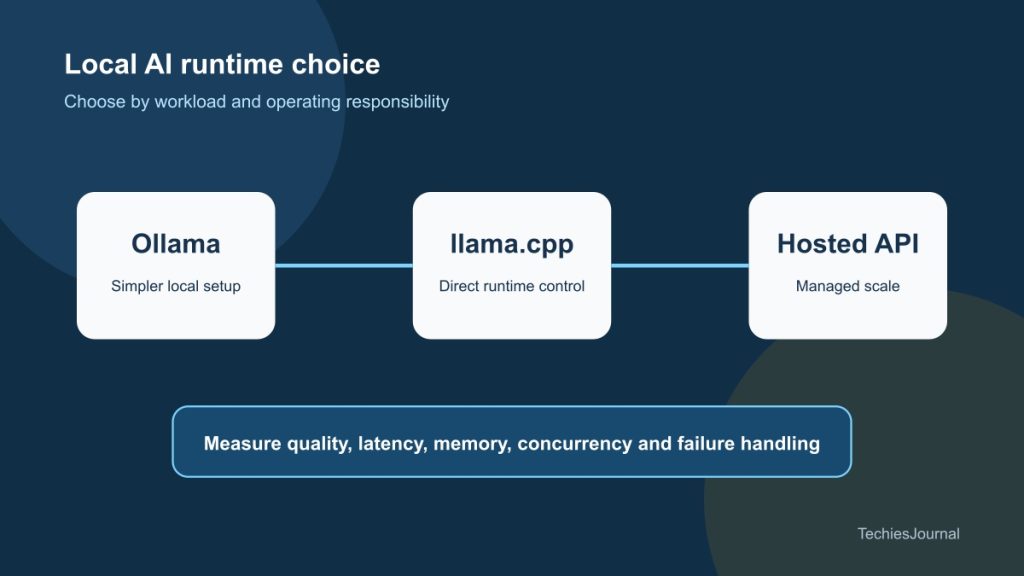
एक developer साबित करता है कि AI workflow लैपटॉप पर चल सकता है। मॉडल सवालों के जवाब देता है, डेटा निकालता है और संवेदनशील prompts को बाहरी API से दूर रखता है। प्रदर्शन सफल रहता है।
अगला सवाल अधिक कठिन है: प्रदर्शन के बाद इसे किस runtime पर चलाना चाहिए?
Ollama और llama.cpp को अक्सर प्रतिस्पर्धी local AI tools के रूप में पेश किया जाता है। यह तुलना केवल आंशिक रूप से सही है। दोनों developer hardware पर models चला सकते हैं, लेकिन वे अलग स्तरों पर काम करते हैं और उपयोगकर्ता के लिए अलग निर्णय लेते हैं।
Recent releases ने structured output reliability, Apple Silicon performance और hardware support बेहतर किए हैं।[1] इससे local inference अधिक उपयोगी हुई है, लेकिन हर laptop production AI platform नहीं बन गया।
सुविधा चाहिए या सीधा control
llama.cpp C और C++ में बना inference engine और toolset है। यह quantised GGUF models और Metal, CUDA, HIP, Vulkan, SYCL तथा CPU execution जैसे backends को support करता है। इसमें command-line tools, benchmarking utility और OpenAI-compatible server भी हैं।[3]
इससे operator को model files, quantisation, memory use, GPU offload और server behaviour पर सीधा control मिलता है। इसके साथ अधिक निर्णयों की जिम्मेदारी भी operator की होती है।
Ollama model management और serving को सरल बनाता है। यह model retrieval, local storage, configuration और API को छोटे operational surface के पीछे संभालता है। Supported systems पर यह llama.cpp या MLX जैसे engines का उपयोग कर सकता है।
इसलिए Ollama चुनना llama.cpp को अस्वीकार करना नहीं है। यह ऐसा managed layer चुनना हो सकता है जो lower-level inference components को आपके लिए संभाले।
Workload के अनुसार चुनाव करें
| Requirement | Ollama से शुरू करें | llama.cpp सीधे चुनें | Hosted API पर विचार करें |
|---|---|---|---|
| तेज developer setup | अच्छा fit | अधिक setup choices | अच्छा fit |
| Hardware पर direct control | सीमित | अच्छा fit | सामान्यतः उपलब्ध नहीं |
| Private single-user prototype | अच्छा fit | अच्छा fit | Data policy पर निर्भर |
| बदलती हुई अधिक demand | Local hardware से सीमित | Engineering चाहिए | अच्छा fit |
| Offline operation | अच्छा fit | अच्छा fit | कमजोर fit |
| Managed scaling और availability | Team को बनाना होगा | Team को बनाना होगा | सामान्यतः शामिल |
Runtime, quantisation, context length और hardware बदलने पर वही model अलग व्यवहार कर सकती है।
केवल tokens per second को benchmark न करें
Generation speed मापना आसान है और उसे जरूरत से अधिक महत्व देना भी आसान है। उपयोगी local test को पूरा workload cover करना चाहिए।
Interactive tasks के लिए time to first token और batch work के लिए total time मापें। सबसे लंबे expected prompt के साथ memory use दर्ज करें। एक request सफल होने से दस concurrent requests सफल होंगी, यह न मानें।
Structured output को अलग test चाहिए। Ollama JSON schema के अनुसार responses को constrain कर सकता है, लेकिन हर model हर schema को सही नहीं मानेगी।[2] Invalid, incomplete और semantically wrong outputs गिनें।
Tool-using workflows में tool selection, arguments और failure handling जाँचें। तेज model अगर unreliable actions बनाती है, तो वह automation के लिए तैयार नहीं है।
सही तुलना के लिए fixed test pack रखें:
- एक ही model और quantisation
- एक ही prompts और context sizes
- cold-start और warm-run measurements
- valid structured-output rate
- time to first token और completion time
- peak और sustained memory
- concurrent-request behaviour
- वास्तविक task पर answer quality
llama.cpp controlled performance testing के लिए llama-bench देता है।[4] Server workloads के लिए भी benchmark tools हैं।[5] ये किसी दूसरी machine के performance numbers copy करने से अधिक उपयोगी हैं।
Local का अर्थ अपने आप secure नहीं होता
Local inference prompts और documents को hosted model provider से दूर रख सकती है। कुछ prototypes के लिए यह वास्तविक लाभ है। लेकिन यह पूर्ण security boundary नहीं है।
देखें कि model files कहाँ से आईं और licence intended use की अनुमति देता है या नहीं। Server किन network interfaces पर bind होता है, इसे सीमित करें। दूसरी machine को access देने से पहले authentication जोड़ें। तय करें कि prompts, responses और uploaded files log होते हैं या नहीं। Local storage सुरक्षित रखें और experiment खत्म होने पर test data हटाएँ।
Office network पर गलती से exposed laptop service भी exposed service ही है। Download किया गया model भी software supply-chain dependency है।
पहचानें कि local inference की सीमा कहाँ है
Learning, private experiments, developer assistance, offline work और low-volume internal tools के लिए local AI मजबूत विकल्प है। Predictable latency under concurrency, large context, very large models, central observability, high availability या rapid failover चाहिए तो यह कठिन हो जाती है।
इस स्थिति में चुनाव केवल local या cloud नहीं होना चाहिए। Team local prototype से task validate कर सकती है और demanding workloads को hosted API या managed inference platform पर ले जा सकती है। Sensitive work local रह सकता है।
Workflow उपयोगी है या नहीं जानने के लिए simplicity चाहिए तो Ollama से शुरू करें। Hardware use पर control चाहिए तो llama.cpp के करीब जाएँ। Runtime चलाना वास्तविक समस्या से ध्यान हटाए तो hosted service चुनें।
Figure 1 के लिए सुगम विवरण
त्वरित local setup के लिए Ollama, सीधे hardware control के लिए llama.cpp और managed scale के लिए hosted API की ओर ले जाने वाला decision map। गोपनीयता, विश्वसनीयता और लागत की जाँच हर विकल्प के लिए आवश्यक है।
आगे पढ़ें
- Ollama releases, Ollama. ↩
- Ollama structured outputs. ↩
- llama.cpp project, ggml-org. ↩
- llama-bench, ggml-org. ↩
- SPEED-Bench server benchmark, ggml-org. ↩