

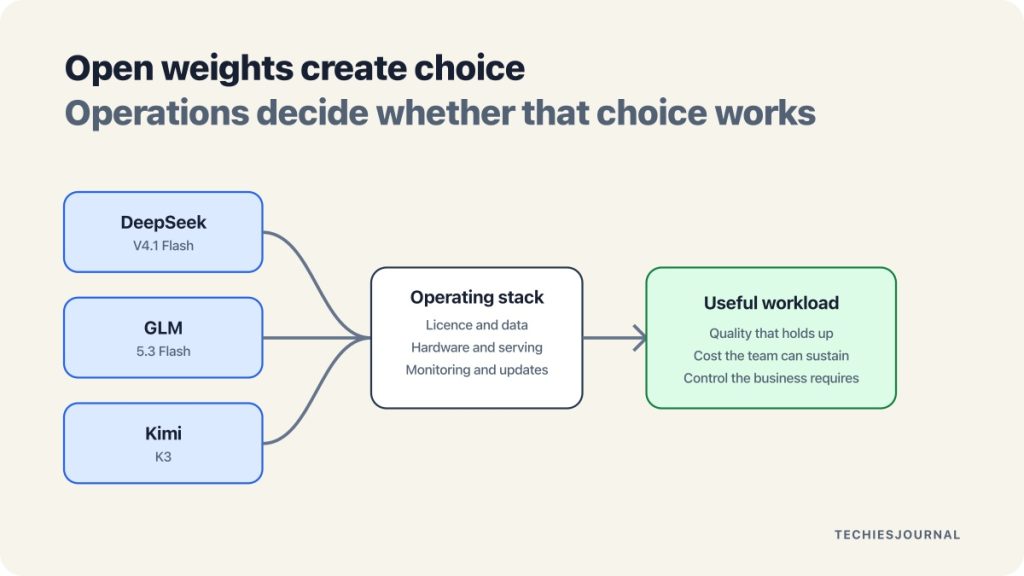
एक engineering team किसी नए model को देखती है। उसके weights उपलब्ध हैं, context window बड़ा है और benchmark दावे मजबूत दिखाई देते हैं। स्वाभाविक प्रतिक्रिया होती है: शायद टीम इसे private environment में चला सकती है, API लागत घटा सकती है और किसी बड़े US model provider पर निर्भरता कम कर सकती है।
यह निष्कर्ष सही हो सकता है। लेकिन यह अपने आप सही नहीं हो जाता।
DeepSeek V4.1 Flash, Z.ai का GLM 5.3 family और Moonshot AI का Kimi K3 दिखाते हैं कि Chinese labs open-weight AI में कितनी तेजी से आगे बढ़ रही हैं। वे उस अंतर को भी सामने लाते हैं जिसे model announcements अक्सर छिपा देते हैं। किसी model को डाउनलोड कर पाना और उसे सुरक्षित, किफायती और भरोसेमंद तरीके से चलाना अलग बातें हैं।
Open weight का अर्थ open source नहीं है
Open-weight model अपने trained parameters डाउनलोड के लिए उपलब्ध कराता है। इससे टीम हर request को developer API पर भेजे बिना model की जाँच, adaptation और self-hosting कर सकती है।
इसका अर्थ यह नहीं कि पूरा training data, training code या training process उपलब्ध है। यह unrestricted commercial use की guarantee भी नहीं देता। हर model की अपनी licence और usage conditions होती हैं।
इन models के लिए यह अंतर महत्वपूर्ण है। DeepSeek ने V4.1 Flash checkpoints और technical details प्रकाशित किए हैं।[1] Z.ai ने GLM 5.3 और GLM 5.3 Flash weights जारी किए हैं।[3] Moonshot ने अपने model licence के अंतर्गत Kimi K3 weights प्रकाशित किए हैं।[5] Procurement या legal review को उसी exact version की जाँच करनी चाहिए जिसे टीम उपयोग करना चाहती है।
चित्र 1 के लिए टेक्स्ट विवरण
छह-स्तरीय स्टैक यह दिखाता है कि प्रकाशित मॉडल वेट्स को एक उपयोगी AI सेवा बनने से पहले लाइसेंस समीक्षा, बुनियादी ढाँचा, इन्फरेंस सर्विंग, गवर्नेंस और वर्कलोड मूल्यांकन की आवश्यकता होती है।
तीन models, तीन अलग operating questions
Headline features एक ही business question का उत्तर नहीं देते।
| Model | Documented design signal | टीम को क्या पूछना चाहिए |
|---|---|---|
| DeepSeek V4.1 Flash | 552 billion backbone parameters. Decoding के समय 16 billion और prompt processing के समय 8 billion parameters active होते हैं। One million tokens तक support करता है। | क्या compressed context design लंबे, input-heavy agent workloads की serving cost घटा सकता है? |
| GLM 5.3 Flash | 320 billion total parameters और 18 billion active parameters. Native multimodal support और efficiency-focused hybrid attention design. | क्या बड़ा GLM 5.3 चलाए बिना faster model टीम की coding और multimodal जरूरतें पूरी कर सकता है? |
| Kimi K3 | 2.8 trillion parameter multimodal model, one-million-token context window और published weights. | क्या इसकी capability बहुत बड़े hosting और operational footprint को उचित ठहराती है? |
ये vendor-documented specifications हैं। ये साबित नहीं करते कि कोई एक model हर स्थिति में बेहतर है। Provider, reasoning setting, quantisation method और evaluation harness बदलने पर independent results भी बदलते हैं।[7] Leaderboard rank evaluation शुरू कर सकता है, समाप्त नहीं।
Mixture of experts compute घटाता है, model storage नहीं
तीनों model families mixture-of-experts, या MoE, design का उपयोग करती हैं। हर token के लिए सभी parameters उपयोग करने के बजाय model network का केवल एक हिस्सा activate करता है।
इससे प्रत्येक response के लिए computation घट सकता है। लेकिन inactive weights गायब नहीं होते। System को बहुत बड़े model को GPU memory, host memory और storage में रखना और इनके बीच ले जाना पड़ सकता है।
इसीलिए active-parameter संख्या को अकेले देखना भ्रमित कर सकता है। कोई model 16 billion parameters activate कर सकता है, फिर भी उसे सैकड़ों billion parameters load और coordinate करने पड़ सकते हैं। Network links, memory bandwidth, inference kernels, cache management और parallel serving वास्तविक product का हिस्सा बन जाते हैं।
ये सामान्य laptop models नहीं हैं। छोटे quantised variants उपलब्ध हो सकते हैं, लेकिन community quantised build को अलग artefact के रूप में evaluate करना चाहिए। उसका व्यवहार vendor के hosted model जैसा ही होगा, यह मानना ठीक नहीं है।
Long context capacity है, guaranteed understanding नहीं
One-million-token context windows अब इस competition का प्रमुख हिस्सा हैं। वे बड़े codebases, document collections और लंबे agent sessions में उपयोगी हो सकते हैं।
लेकिन context capacity यह साबित नहीं करती कि model सही detail खोजेगा, instructions बनाए रखेगा या पूरी window पर लगातार सही reasoning करेगा। Longer prompts processing time, cache requirements और cost भी बढ़ाते हैं।
DeepSeek V4.1 Flash technically दिलचस्प है क्योंकि यह इस operating problem को सीधे address करता है।[1] उसका paper input-heavy workloads के लिए compressed attention और छोटे key-value caches का वर्णन करता है। यह वास्तविक bottleneck के लिए architectural response है। फिर भी टीम को अपने data पर retrieval accuracy, time to first token और end-to-end task completion जाँचना होगा।
API price और self-hosting cost अलग calculations हैं
Low API price की तुलना आसान है। Self-hosting cost GPUs, power, engineering time, monitoring, security, upgrades और spare capacity में बंटी होती है।
Predictable demand वाली busy service dedicated infrastructure को उचित ठहरा सकती है। Irregular traffic वाली छोटी team API calls से अधिक पैसा idle GPUs पर खर्च कर सकती है। Privacy, data location, customisation या provider independence सबसे महत्वपूर्ण हो तो hosting फिर भी सही विकल्प हो सकता है।
इसलिए comparison cost per token के बजाय cost per successful task पर होना चाहिए। अधिक retries लेने वाला, लंबे answers देने वाला या tool calls में असफल होने वाला cheaper model पूरे workflow में अधिक महँगा पड़ सकता है।
Practical evaluation order
Hardware खरीदने से शुरुआत न करें। Workload से शुरुआत करें।
- सामान्य काम और difficult edge cases दिखाने वाले बीस से पचास real tasks चुनें।
- Private cluster बनाने से पहले hosted model या trusted inference provider को test करें।
- Task success, latency, tool-use reliability, output length और human correction time मापें।
- Model licence, data path, logging policy और regional requirements की review करें।
- Realistic utilisation, redundancy और engineering support के साथ self-hosting estimate बनाएँ।
- Private hosting pilot तभी चलाएँ जब वह ऐसी requirement हल करता हो जिसे API route पूरा नहीं कर सकता।
अधिकांश teams के लिए तत्काल lesson यह नहीं है कि उन्हें DeepSeek, GLM या Kimi को self-host करना चाहिए। Lesson यह है कि अब evaluate करने के लिए अधिक credible models हैं और AI work कैसे deliver होगा, यह चुनते समय teams के पास अधिक leverage है।
Chinese open-weight model race विकल्प बढ़ा रही है। Enterprise के लिए सही model वह नहीं होगा जिसके parameter सबसे अधिक हों या launch chart सबसे मजबूत हो। सही model वह होगा जो team की cost, control और operational limits के भीतर आवश्यक काम पूरा करे।
References and further reading
- DeepSeek V4.1 Flash technical paper, DeepSeek AI, September 2026. Architecture, context और cache-compression details. ↩
- DeepSeek V4.1 Flash model repository, DeepSeek AI. Checkpoints, model card और licence. ↩
- GLM 5.3 release, Z.ai, August 2026. Model और intended workloads की vendor explanation. ↩
- GLM 5.3 Flash release, Z.ai, August 2026. Smaller active model के architecture और efficiency claims. ↩
- Kimi K3 technical article, Moonshot AI, July 2026. Model design, evaluations और release context. ↩
- Kimi K3 model repository, Moonshot AI. Published weights, model card और licence. ↩
- Kimi K3 independent model analysis, Artificial Analysis. Provider, performance और cost comparisons. ↩