

Your servers can be fine and you can still be down
If the servers are still running, why is the service down?
Many outage stories sound the same: something broke at the cloud provider, so our application stopped. Four incidents from the past year show a pattern that is easy to miss. The first fault was not always in the part serving users, and even when it was, the damage spread or lasted because of the part that starts, updates and routes the work.
That part has a name. This article explains it, walks through what happened in each incident, and ends with five questions you can ask about your own design.
Two jobs inside every cloud
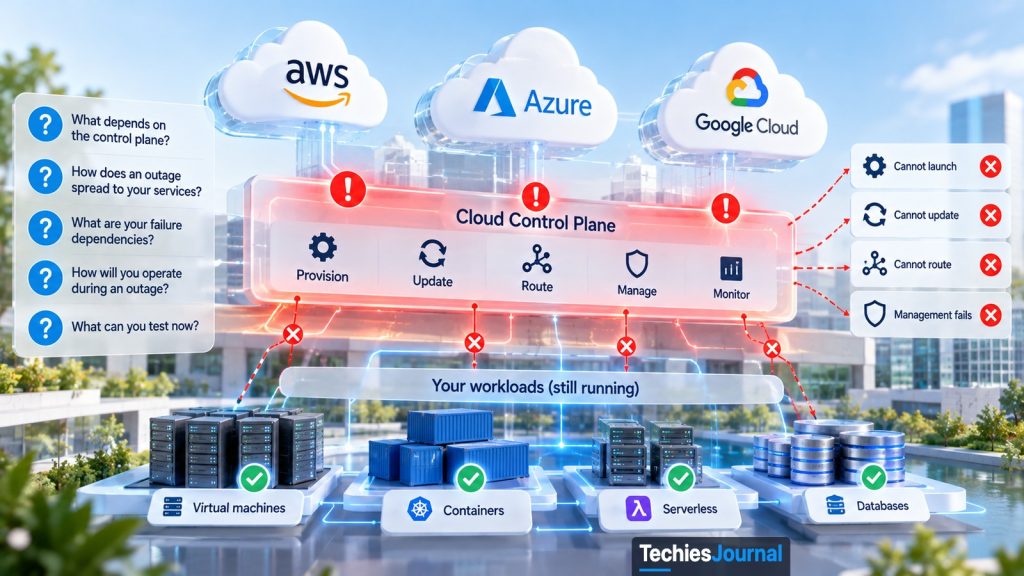
A cloud does two jobs. The first is running your work: answering requests, storing data and moving network traffic. This is called the data plane.
The second is managing that work: launching machines, applying settings, checking health and deciding where traffic goes. This is called the control plane. You touch it whenever you scale up, deploy, fail over or sign in with a cloud identity.
Most of the time you do not notice the difference. In an outage you do, because a service can be healthy on the data plane and still impossible to repair on the control plane.
Select an incident in the figure to read its details.
Select an incident to read its details.
1. AWS, October 2025
- What failed first
- A latent race condition in AWS’s DNS management system let an old plan overwrite a newer one, and a cleanup step then deleted the old plan. That left the DNS record for the regional DynamoDB endpoint empty, and operators had to step in.
- What spread or prolonged it
- After DynamoDB came back, the system that manages EC2 hosts fell into what AWS calls congestive collapse, so new EC2 instances could not launch until 10:36 AM. Load balancer health checks alternated between failing and healthy, and the automatic failover took capacity out of service until engineers switched it off at 9:36 AM.
- How long
- DNS was restored by 2:25 AM Pacific time on 20 October. EC2 launches failed until 10:36 AM and load balancer errors ran to 2:09 PM.
- What the provider changed
- AWS disabled the DNS Planner and Enactor automation worldwide pending a fix. This is AWS’s statement at the time, and the current status is unknown.
2. Google Cloud, 20 October 2026
- What failed first
- Power to the building that hosts one zone in London (europe-west2-b) was interrupted. Both the primary and backup controllers failed to start the generators, so the batteries ran down and everything in that zone lost power. Google’s final report points to a misconfiguration in the controllers.
- What spread or prolonged it
- Calls from regional services to the offline zone timed out, and traffic that failed over to the other zones used up their capacity.
- How long
- The outage ran from 06:00 to 12:08 UTC. New virtual machine creation resumed at 04:46 Pacific time, which is 11:46 UTC.
- What the provider changed
- Google’s repair list was still open when this article was written.
3. Azure, 30 September 2026
- What failed first
- Microsoft had paused operating system updates on a group of network gateways. When the pause ended, many updates started at once.
- What spread or prolonged it
- The updates flooded a shared regional control plane that a recent change had already made slower. Microsoft’s review says its throttling and load protection “did not sufficiently protect critical processing”. On some ExpressRoute gateways, a restarting gateway was marked healthy too early, so the update moved on to its backup, and some connections to on-premises networks dropped until the gateways reverted to their last good settings.
- How long
- Impact ran from 20:30 UTC to 02:15 UTC, starting on 30 September.
- What the provider changed
- The repair list includes resuming paused updates in stages.
4. GitHub, 7 October 2026
- What failed first
- An internal service decides which database servers receive writes. During routine maintenance, a replacement machine started with stale records that still listed retired servers.
- What spread or prolonged it
- The machine sent writes to servers that no longer existed. The second time, GitHub says an automated maintenance task put the machine back in charge without honouring a pause.
- How long
- Writes failed for about ten minutes each time.
- What the provider changed
- The status pages this article cites state no change.
Four incidents
AWS, October 2025
This is a year old, but it is the most detailed account AWS has published. In the us-east-1 region, the DNS record for the regional DynamoDB endpoint ended up empty. AWS says a latent race condition in its DNS management system let an old plan overwrite a newer one, and a cleanup step then deleted the old plan, which removed every address from the record. The automation could not repair itself, so operators had to step in.
The record was restored by 2:25 AM Pacific time on 20 October, yet customers kept failing for hours. New EC2 instances could not launch until 10:36 AM, and the system that manages EC2 hosts had fallen into what AWS calls congestive collapse once DynamoDB came back. Load balancers were hit too. AWS says health checks alternated between failing and healthy, which removed nodes from DNS, and for load balancers spread across zones the automatic failover took capacity out of service. Engineers switched that failover off at 9:36 AM.
Fixing the cause took under three hours. Recovering from it took about twelve more.
Google Cloud, 20 October 2026
Power to the building that hosts one zone in London (europe-west2-b) was interrupted. Google’s report says both the primary and backup controllers failed to start the generators, so the batteries ran down and everything in that zone lost power. Workloads that lived only in that zone became unreachable.
The damage spread past the zone because of the control plane. Google says calls from regional services to the offline zone timed out, and traffic that failed over to the other zones used up their capacity. The outage ran from 06:00 to 12:08 UTC, and new virtual machine creation resumed at 04:46 Pacific time, which is 11:46 UTC. Google’s final report points to a misconfiguration in the controllers, and its repair list was still open when this was written.
Azure, 30 September 2026
Microsoft had paused operating system updates on a group of network gateways. When the pause ended, many updates started at once and flooded a shared regional control plane that a recent change had already made slower. Microsoft’s review says its throttling and load protection “did not sufficiently protect critical processing”.
On some ExpressRoute gateways, a restarting gateway was marked healthy too early, so the update moved on to its backup. Some connections to on-premises networks dropped until the gateways reverted to their last good settings. Impact ran from 20:30 UTC to 02:15 UTC. The repair list includes resuming paused updates in stages.
GitHub, 7 October 2026
An internal service decides which database servers receive writes. During routine maintenance, a replacement machine started with stale records that still listed retired servers, and sent writes to servers that no longer existed. Writes failed for about ten minutes each time. The second time, GitHub says an automated maintenance task put the machine back in charge without honouring a pause.
This one was short, but it fits the pattern.
What the four have in common
Reading the four reports side by side, three patterns show up. They are our reading of the reports, not a finding any provider published.
First, the failing part sat in the path to recovery. AWS needed DynamoDB to repair EC2. Google’s regional control services kept waiting on a zone that was dark. Azure’s repair needed a control plane that was already overloaded.
Second, automation was part of the cause in three of them: AWS’s DNS management, Azure’s resumed updates and GitHub’s maintenance task. Third, failover itself created load: Google’s surviving zones were swamped and AWS’s load balancer failover removed capacity.
None of this means the cloud is unreliable overall. These are four reports, from four providers, written by the providers. It does mean that “multiple zones” is not a full answer if starting capacity in the other zones depends on a control plane that is also struggling.
Five questions for your own design
- If a zone disappeared, could you stay up without launching anything new?
- Which of your recovery steps call a provider API: autoscaling, redeploying, changing DNS, signing in with a cloud role?
- Does your failover push extra load onto the places that are still healthy, and do your retries make a slow system slower?
- Do your own configuration changes reach every server at once, or in stages?
- Have you tried the recovery path with the provider’s control plane slow or unavailable, or only with it working?
Spare capacity costs money, and many systems are fine with an hour of downtime. The point is to make that choice on purpose. Question 1 is the hardest to test, because it needs a careful rehearsal or a real zone failure.
How deeply to learn this
Know: anyone who uses cloud services should know that running and manageable are different things, and what control plane and data plane mean.
Use: engineers who run production on a cloud should be able to list which recovery steps depend on provider APIs and which do not.
Master: architects and reliability engineers decide how much capacity stays pre-provisioned, how failover and retries are limited, and how configuration rolls out in stages.
What you can ignore for now
Skip provider league tables and uptime percentages from these four events. Skip the exact timelines unless you are writing a review, because the providers have published them and some are still being revised. You do not need to learn each provider’s internal service names to ask the five questions.
What to do next
Pick one service you run. Write down what would have to be created, changed or called, in the provider’s control plane, to keep it up if one zone went dark tomorrow. Anything on that list is a dependency you can test, shorten or accept.
Before you rely on a failover plan, find out what it needs from the provider while the provider is struggling.
What we know and what we do not
| Claim | Type | Source |
|---|---|---|
| The AWS DynamoDB DNS outage was 19 to 20 October 2025, caused by a race condition that left an empty DNS record | AWS’s own summary | AWS post-event summary |
| DNS was restored by 2:25 AM PDT but EC2 launches failed until 10:36 AM and load balancer errors ran to 2:09 PM | AWS’s own summary | AWS post-event summary |
| AWS disabled the DNS Planner and Enactor automation worldwide pending a fix | AWS statement at the time. Current status unknown | AWS post-event summary |
| Google’s europe-west2 outage ran 06:00 to 12:08 UTC on 20 October 2026 after a power interruption and generator controller failure | Google’s incident report, read through a page summary | Google Cloud incident |
| Cross-zone control-plane calls and failover load spread the impact beyond the one zone | Google’s incident report, read through a page summary | Google Cloud incident |
| Google’s final report attributes the controller failure to a misconfiguration of the controller logic | Google’s final report. The phrase was checked on the page | Google Cloud incident |
| Azure’s 30 September gateway incident came from resumed paused updates hitting a slowed shared control plane | Microsoft’s post incident review, read through a page summary | Azure status history, entry 7Q30-010 in the list. The page has no permalink for it |
| GitHub’s 7 October write outages came from a machine with stale routing records | GitHub status posts | GitHub incident of 7 October, first outage and recurrence |
Go deeper
- AWS: Summary of the Amazon DynamoDB service disruption in the Northern Virginia region, for the full timeline and AWS’s corrective actions.
- Google Cloud incident Xs2XTHzAVC9YnafnPyzj, for the preliminary and final reports.
- Azure status history, for the post incident review 7Q30-010 of 30 September (find it in the list, there is no direct link).
- GitHub status: incident of 7 October and the recurrence.
- Related on this site: Cloud Capacity Is Not Cloud Availability, which covers the launch-failure side of the same problem.
Facts in this article were checked on 30 October 2026. Providers are still publishing and revising their reviews, so check the sources above before you act.