

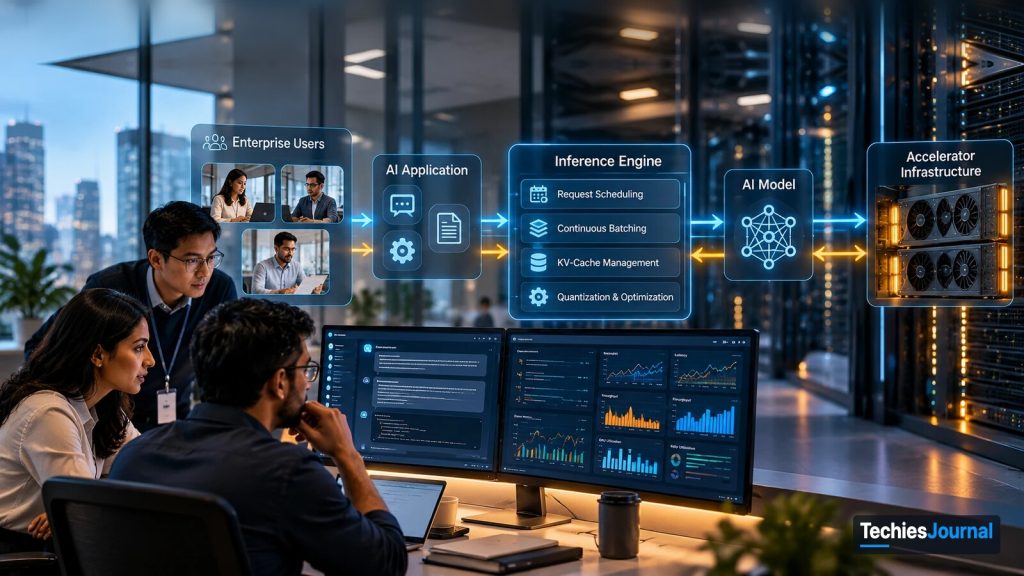
Illustrative AI serving stack. The dashboards and charts shown are decorative, not real measurements.
Running an AI model is one thing. Making it respond reliably to many users is another. Understanding inference engines helps engineering teams make better serving decisions without relying on misleading performance comparisons.
How an AI model answers a question
Imagine an organization building an internal AI assistant. Employees can use it to search technical documents, understand internal procedures, and ask questions about applications and infrastructure.
The development team selects an open-weight language model, runs it on a GPU-equipped machine, and connects it to a simple chat interface. During the demonstration, everything works. An employee asks a question, the model processes it, and a response appears.
This process is called inference. A model learns patterns during training. During inference, it uses its trained parameters to process new inputs and generate outputs. It does not normally retrain itself whenever someone asks a question.
Language models produce responses as sequences of tokens, which may represent words, parts of words, or punctuation. Generating those tokens requires computation and memory, with resource requirements varying by model and workload. For a single-user demonstration, managing that computation may seem straightforward. Production introduces a different set of challenges.
What an AI inference engine does
An AI model and an inference engine serve different purposes. The model contains the trained parameters and computational structure used to generate outputs. The inference engine is the software responsible for executing that model on available hardware and managing the associated computational work.
Depending on its design, an inference engine can load models, schedule requests, manage memory, batch operations, and stream generated responses.
The basic relationship is:
User → AI application → Inference engine → Model execution → Response
A production application may also include document retrieval, authentication, network routing, monitoring, and other services. The inference engine does not replace those components.
Tools such as Ollama, LM Studio, and llama.cpp make local model execution accessible, with varying levels of serving capability. Systems such as vLLM, SGLang, and LMDeploy offer additional approaches for managing inference workloads. The next section explains why an organization needs these capabilities instead of continuing with the setup that worked during development.
Why production changes the problem
The organization makes its assistant available to several hundred employees. Some ask short questions. Others submit lengthy documents. Multiple requests arrive simultaneously, and responses vary considerably in length.
These requests do not consume equal computing resources. Processing a long document requires more input computation than processing a short question. Generating a lengthy response also requires more work than producing a brief answer.
As concurrent usage grows, the serving system must manage competing requests and limited GPU memory. Employees may experience inconsistent response times even when the available hardware appears powerful.
The problem is no longer simply whether the model can generate an answer. It is whether the serving system can handle different requests efficiently while maintaining acceptable performance.
How inference engines manage concurrent requests
For many transformer-based language models, inference involves two important stages. Prefill is the stage in which the model processes the input tokens and prepares the information needed for generation. Longer inputs generally create more work at this stage.
Decode is the stage in which the model generates output tokens through successive computational steps. The two stages have different computational characteristics. Their resource demands depend on the model, hardware, request lengths, and execution configuration.
When multiple requests arrive, efficient scheduling becomes important. One technique is continuous batching. Rather than processing a fixed group of requests until all have finished, the engine can adjust the active group as requests complete and new requests become ready. This can improve hardware utilization and throughput.
Memory management is equally important. During generation, transformer models commonly retain intermediate attention information from previously processed tokens. This is called the key-value cache, or KV cache. Retaining this information avoids repeating certain calculations, but the cache consumes memory. More concurrent requests and longer sequences generally increase memory requirements.
Inference engines use different strategies to manage that memory. For example, vLLM introduced PagedAttention, an approach that organizes KV-cache memory into blocks to reduce inefficient allocation and improve memory utilization.
These techniques help explain how an inference engine can improve performance without changing the underlying model. Source: vLLM documentation
Accessible text alternative for this figure
Inside the engine, requests of different lengths arrive together. A scheduler applies continuous batching, the prefill stage processes the input tokens, the decode stage generates output tokens one at a time, and the response is streamed back to the user. A KV cache in accelerator memory supports the scheduler, prefill and decode, and grows with more concurrent requests and longer sequences.
Around the engine, an API gateway may handle authentication and request limits, the application may handle sessions, document retrieval, tool authorization and timeouts, an orchestration platform may supervise the serving process, and monitoring should join engine metrics with application-level behavior.
Other optimizations
As workloads become more demanding, additional techniques may help.
Quantization uses reduced numerical precision for certain model values or computations. It can lower memory requirements and potentially improve performance, although compatibility and output quality must be assessed.
Prefix caching reuses suitable computations when requests share identical prompt prefixes. This may help applications that repeatedly send the same instructions or context.
Speculative decoding uses proposed tokens and a verification process to accelerate generation under favorable conditions.
Some deployments also separate prefill and decode execution or distribute model computation across accelerators. Not every application benefits equally from these methods. Feature support and effectiveness depend on the model, engine version, hardware, and workload.
Understanding these mechanisms gives engineers a foundation for evaluating the engines that implement them.
Understanding the available inference engines
Several open-source projects provide inference execution and serving capabilities. Their features overlap, but their architectures, compatibility, and operational characteristics can differ.
vLLM
vLLM is an open-source inference and serving engine associated with efficient KV-cache management through PagedAttention. It supports capabilities such as continuous batching, prefix caching, quantization, speculative decoding, structured outputs, and distributed execution.
It is a relevant candidate for multi-user model-serving environments, although individual features depend on the model, hardware, backend, and version. Source: vLLM documentation
SGLang
SGLang provides language-model inference and serving capabilities, including execution scheduling, cache-related optimizations, structured generation, and tool-calling support. It also offers benchmarking tools for evaluating offline execution and online serving.
These capabilities make it relevant to applications with demanding serving requirements, but they do not establish that it is universally faster for agentic workloads. Source: SGLang documentation
LMDeploy
LMDeploy supports model serving through execution backends including TurboMind and PyTorch. It provides quantization options, serving interfaces, and performance-evaluation tools.
Its model support and optimization capabilities vary by backend, making compatibility checks particularly important. Source: LMDeploy documentation
Where llama.cpp fits
llama.cpp is another relevant inference runtime, particularly for portable execution, quantized models, and resource-constrained hardware. It also provides serving capabilities and can be appropriate for some production environments.
A smaller application with predictable traffic may not need a more complex serving architecture. More demanding workloads may justify evaluating additional engines. The practical question is not which project is most popular, but which implementation supports the application’s actual requirements.
| Engine | What its documentation highlights | What to check first |
|---|---|---|
| vLLM | KV-cache management with PagedAttention, continuous batching, prefix caching, quantization, speculative decoding, structured outputs, distributed execution | Which of these features your model, hardware, backend and version support |
| SGLang | Execution scheduling, cache-related optimizations, structured generation, tool calling, benchmarking tools for offline and online serving | Whether its strengths apply to your workload, because they do not make it universally faster for agentic work |
| LMDeploy | TurboMind and PyTorch backends, quantization options, serving interfaces, performance-evaluation tools | Model support and optimizations that vary by backend |
| llama.cpp | Portable execution, quantized models, resource-constrained hardware, serving capabilities | Whether a smaller application with predictable traffic needs a more complex engine |
Before comparing speed, verify compatibility
Our internal assistant now needs to support ordinary conversations, document-based questions, structured responses, and certain tool-using workflows. The team shortlists several inference engines.
Before benchmarking them, it must verify that each candidate can run the application correctly. Important checks include model and tokenizer compatibility, supported context length, hardware requirements, chat templates, streaming, structured outputs, and tool-call behavior.
Two engines may expose OpenAI-compatible APIs without behaving identically. They can differ in supported parameters, model-specific templates, constrained-generation behavior, and tool-call parsing.
For example, an engine might generate text quickly but return JSON that does not satisfy the application’s required schema. Similarly, tool-call output may require model-specific configuration before the application can interpret it reliably.
The inference engine may help produce a tool-call request, but the application remains responsible for authorizing and executing the requested action. Performance comparisons are meaningful only after the candidates satisfy the same functional requirements.
An engine that cannot reliably produce application-valid outputs should not win because it generates more tokens per second.
How to measure inference performance
Once compatibility is established, performance testing can begin. The first question is what users actually experience.
When an employee submits a request, there may be a delay before the first token appears. The response then arrives over time until generation finishes. Different measurements describe different parts of that experience.
| Metric | Meaning | Practical relevance |
|---|---|---|
| Time to first token (TTFT) | Delay before the first generated token arrives | Interactive responsiveness |
| Inter-token latency (ITL) | Time between successive generated tokens | Smoothness of streamed responses |
| End-to-end latency | Total time until the response completes | Full task-completion time |
| Throughput | Requests or tokens completed per unit of time | Serving capacity |
| Successful request rate | Requests completed according to application requirements | Effective usable capacity |
An engine can achieve high throughput while some individual requests experience longer delays. The preferred balance depends on the workload. For a conversational assistant, fast initial responses may be important. For overnight document processing, total throughput and operating cost may matter more.
Why averages can be misleading
Average latency does not reveal the full distribution of response times. A system may serve most requests quickly while a smaller percentage experiences substantial delays.
Engineers therefore examine percentiles such as P95 and P99. For example, P95 latency identifies a value at or below which approximately 95% of measured requests completed.
Performance evaluation should also include errors, timeouts, cancellations, and invalid responses. Excluding failed requests can make a system appear more efficient than it is. Source: NVIDIA AIPerf metrics reference
Why inference-engine benchmarks disagree
A benchmark might report that SGLang outperforms vLLM. Another may report the opposite. The results are not necessarily contradictory.
Performance depends on the model architecture, model size, precision, accelerator, concurrency, input and output lengths, and serving configuration. A benchmark performed with a small model on one GPU does not establish the preferred engine for a larger model distributed across multiple accelerators. Even identical hardware does not guarantee a fair comparison if engines use different optimization settings.
Engineers should therefore distinguish between two kinds of evaluation:
- Controlled comparison: Hold as many variables constant as possible to understand the differences between engines.
- Best practical configuration: Optimize each candidate appropriately to determine which deployment meets the application’s requirements most effectively.
Both are useful, but they answer different questions.
Offline versus online benchmarks
An offline benchmark can measure model execution without the full API-serving path. An online benchmark sends requests to a running service, incorporating additional effects such as request handling and scheduling.
An offline result should not be directly compared with an online result as though they measure identical conditions. SGLang’s serving benchmark guide describes workload generation and performance testing across supported serving backends.
Industry benchmarks also continue to develop. MLPerf Inference v6.1, released in September 2026, expanded attention to workloads such as end-to-end retrieval-augmented generation and agentic inference. These developments improve the methods available for evaluating inference systems, but they do not identify one engine as best for every application. Source: MLCommons, MLPerf Inference
Build a benchmark around the application
For our enterprise assistant, a useful test should include three representative workloads. Short questions reveal interactive responsiveness. Long-document requests expose input-processing and memory demands. Structured-output and tool-using requests test correctness alongside performance.
The team should increase concurrency gradually and observe how each engine behaves under heavier traffic. For reproducibility, the test record should identify the exact model revision, engine version, hardware, numerical precision, optimization settings, and measurement method.
The final comparison should consider latency percentiles, throughput, errors, resource consumption, and successfully completed application-valid requests. The objective is not to produce a universal leaderboard. It is to determine which configuration meets this application’s requirements.
What an inference engine does not protect you from
A benchmark usually measures an engine in comfortable conditions, so the test should also find the point where the conditions stop being comfortable. When the KV cache cannot hold every request in a batch, the engine has to do something with the extra work. vLLM, for example, can preempt a request and recompute it later, and its documentation warns that this can adversely affect end-to-end latency. Source: vLLM optimization and tuning guide
Other engines handle memory pressure in their own ways. For each candidate, ask what happens to a request when memory runs out: does it wait, restart, slow everyone down or fail, and can the application tell the difference?
An inference engine is also not a security boundary by default. The vLLM security guide says its API key setting protects only certain endpoint prefixes, lists other endpoints that stay reachable without a key, and recommends minimizing exposed endpoints and placing the server behind a reverse proxy. It also states that communication between nodes in a multi-node deployment is insecure by default and must be protected by an isolated network. Source: vLLM security guide
The practical rule is that authentication, request limits and network isolation belong to the gateway and platform layers described above, and that the engine should not be exposed directly to users or untrusted networks. For any other engine, read its security documentation before assuming it behaves the same way.
Recovery needs preparation before the first incident. Record the exact model revision and engine version in production as well as in benchmarks, keep the previous engine image deployable, and send a new version to a small share of traffic before moving everyone.
Then test the unpleasant cases on purpose: a restart in the middle of busy traffic, a model that fails to load, and a rollback, and measure how long users are affected. An engine upgrade can change supported parameters, templates and tool-call behavior, so the compatibility checks from earlier need to be repeated after every upgrade.
What happens after deployment
A strong benchmark result does not establish production reliability. The serving system must also handle request cancellation, resource exhaustion, unexpected traffic, failed model loads, restarts, and software upgrades.
These responsibilities extend beyond the inference engine. An API gateway may manage authentication and request limits. An orchestration platform may supervise the serving process. The application may control sessions, document retrieval, tool authorization, and timeouts. The team needs to establish where each responsibility belongs.
Monitoring and troubleshooting
Suppose employees report slower responses. The team should be able to determine whether the cause is increased traffic, longer prompts, request queues, memory pressure, model execution, or a downstream application dependency.
Inference engines commonly expose operational metrics. For example, vLLM provides Prometheus-compatible metrics for its serving environment. Useful observability requires connecting those engine metrics with application-level behavior.
If document retrieval consumes most of the request time, changing inference engines may provide little improvement. Monitoring only the GPU is not enough to explain the complete user experience.
Faster inference can reduce costs, but not automatically
Greater throughput may allow a heavily utilized deployment to serve more requests with the same hardware or reduce the number of accelerator instances required. However, increasing throughput on a lightly used, continuously billed GPU may not reduce spending. The economic assessment should account for infrastructure charges, utilization, successful requests, engineering effort, maintenance, and operational complexity.
A useful comparison measures the cost of meeting the application’s service requirements, not simply the cost per theoretical token.
How a team can choose an inference engine
Our internal assistant began as a single-user demonstration. It now requires reliable serving across multiple request types and users. The engineering team has enough understanding to approach the decision systematically.
First, it should decide whether self-managed inference is necessary. A managed inference service may already meet the application’s requirements while reducing infrastructure responsibilities. If self-managed serving is justified, the team can evaluate compatible engines.
| Decision | What to establish |
|---|---|
| Deployment approach | Managed service or self-managed serving |
| Compatibility | Required model, hardware, outputs, and integrations |
| Performance | Latency, throughput, and behavior under realistic traffic |
| Reliability | Resource limits, failures, monitoring, and recovery |
| Economics | Infrastructure costs, operational effort, and migration value |
Sometimes the existing engine will remain the best practical option. A competing engine may offer higher throughput but introduce compatibility or maintenance costs that outweigh the improvement. There is no requirement to migrate because another product leads a public benchmark.
Likewise, a simpler runtime may be sufficient for an application whose performance and reliability requirements are already satisfied. The decision should follow measurable application requirements, not technology popularity.
How deeply professionals need to understand inference engines
Different roles require different levels of knowledge.
Application developers should understand response latency, API compatibility, streaming, output validation, and the implications of their model requests.
Platform engineers and SREs operating inference infrastructure need deeper knowledge of resource utilization, concurrency, monitoring, deployment, reliability, and capacity planning.
AI infrastructure specialists optimizing model execution may also need to understand scheduling algorithms, KV-cache management, quantization, parallelism, and accelerator-specific techniques.
Not everyone needs to master inference-engine internals. The appropriate depth depends on whether a professional consumes, operates, or optimizes the serving infrastructure.
Making the right engineering decision
AI models attract attention because their outputs are visible. Inference engines operate behind those outputs, managing the computational work that makes production serving possible. Their importance becomes clearer when applications face concurrent traffic, variable request lengths, memory constraints, and service-level requirements.
Choosing an inference engine therefore requires more than comparing benchmark numbers. Engineers need to verify application compatibility, test representative workloads, understand operational responsibilities, and evaluate the total cost of meeting service requirements.
Products and benchmark rankings will continue to change. The underlying decision remains the same.
Choose the inference engine that meets the application’s requirements with acceptable performance, reliability, cost, and operational complexity, not simply the one that performs best in someone else’s benchmark.
Go deeper
- vLLM, Official Documentation, vLLM project. Engine architecture, PagedAttention, scheduling, model compatibility, and serving features.
- SGLang, Official Documentation, SGLang project. Model execution, structured generation, tool calling, and deployment capabilities.
- SGLang, Serving Benchmark Guide, SGLang project. Workload generation, concurrency, and online-serving measurements.
- LMDeploy, Official Documentation, LMDeploy project. TurboMind and PyTorch execution backends, model support, and serving.
- llama.cpp, Official Repository, llama.cpp project. Portable inference, quantized execution, and server capabilities.
- NVIDIA, AIPerf Metrics Reference, NVIDIA. Definitions of inference latency, throughput, and related measurements.
- MLCommons, MLPerf Inference, MLCommons. Benchmark methodology and published inference-system results.
- vLLM, Optimization and Tuning, vLLM project. Preemption and KV-cache memory pressure.
- vLLM, Security, vLLM project. Endpoint protection and inter-node communication.
Research cutoff: October 20, 2026. Exact feature availability and compatibility should be verified against the engine release being evaluated.
Related reading on TechiesJournal
- Why AI Inference Is Changing the Way We Think About Load Balancing for how requests are routed across inference replicas once one server is not enough.
- Running Open AI Models Yourself: What It Actually Takes for the self-hosting decision that comes before choosing an engine.