

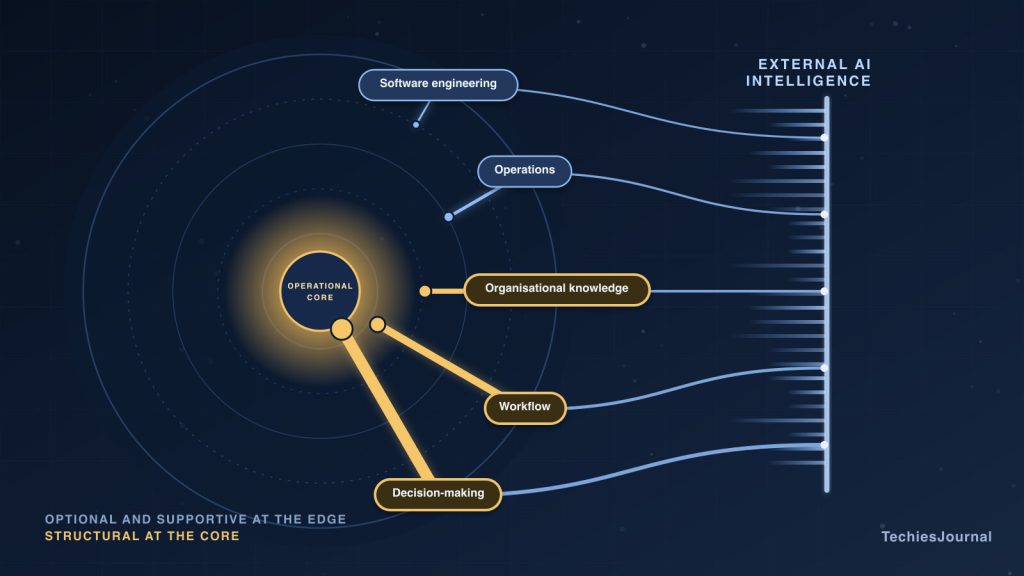
AI adoption often begins with a straightforward business case. A coding assistant helps developers work faster. An agent handles repetitive operational work. A model summarizes documents that previously took employees hours to review.
A decision service classifies requests or chooses which workflow should run next. Each use can make sense on its own.
The economics can also be attractive. A company may complete more work with the same team, reduce repetitive effort and avoid building capabilities that an AI service can provide immediately.
I support that direction.
But as AI moves from helping people to becoming part of how the company itself operates, I think another consideration deserves equal attention:
How much of the company’s capability still belongs to the company?
This is not an argument against external AI providers. Modern businesses already depend heavily on cloud platforms, SaaS products, databases, payment services and many other external technologies.
The difference is that AI is beginning to move into areas that historically contained human judgement, engineering knowledge and application logic. That can create a deeper form of dependency than simply consuming another technology service.
The risk rarely appears on the first day. It develops gradually as the technology succeeds.
Efficiency can quietly become dependency
Consider software development. A company introduces coding agents because they improve productivity. Developers use them to generate code, investigate failures, write tests, review changes and understand unfamiliar parts of the system.
At first, the agent is clearly an assistant. The engineering capability remains inside the organization. But imagine the same company several years later. Agents now perform much of the routine implementation work.
Teams become smaller. Some junior roles disappear. Documentation receives less attention because the agent can inspect the repository when needed.
Engineers become accustomed to asking the model to explain unfamiliar systems rather than building that knowledge themselves. None of those decisions is necessarily wrong. Taken individually, each may be rational.
But together they create an important question:
If that AI capability became unavailable, much more expensive, or unsuitable for the company’s needs, how much of the work could the organization still perform confidently on its own?
That is where efficiency starts becoming an architecture issue.
Accessible text alternative for this figure
Five stages in order. One, AI Assistant: helps a person perform work. Two, Integrated Workflow: AI becomes part of a repeatable business process. Three, Operational Capability: systems and teams expect AI to be available. Four, Structural Dependency: changing the AI layer requires migration, evaluation or organizational adaptation. Five, Deliberately Managed Dependency: the organization retains knowledge, evaluation, fallback and provider-change capability. The aim is managed dependency, not escape from AI. This is TechiesJournal analysis.
We have already seen one side of this problem
In an earlier TechiesJournal Perspective, When AI Does the Junior Work, Who Develops the Next Generation of Professionals?, I looked at the effect of automating the work through which people traditionally gained experience.
The concern was not that junior work must remain manual forever. It was that organizations should understand what else disappears when that work disappears. Routine tasks often do more than produce an immediate output.
They teach people how systems behave. They expose them to mistakes. They build judgement. They develop the senior engineers, analysts and specialists an organization will need later.
There is a parallel risk with AI dependency. When we transfer work to AI, we may also gradually transfer some of the knowledge required to perform that work. The immediate productivity gain is visible. The capability being lost is much harder to see.
That makes this more than a workforce discussion. It becomes an operational-resilience question.
The dependency becomes deeper when AI moves inside the software
Coding agents are still relatively easy to understand because a human engineer remains visibly involved. Decision-oriented AI changes the situation. Traditionally, many software decisions are represented directly in application logic.
For example:
A transaction above a certain threshold requires additional review. A request from one customer category follows one workflow. A particular combination of conditions produces a specific action. The company owns those rules.
It can inspect them, test them, change them and run them without asking an external intelligence service what to do. That model is beginning to expand.
TypeSafe’s Jev, for example, is being developed specifically as a fast decision model for use inside software. Instead of generating long text, it accepts state and produces structured decisions with probabilities.
OpenAI has also introduced its Decisions API in limited preview, designed for tasks such as classification, routing and choosing an application’s next action from predefined possibilities.
These technologies are interesting precisely because they can make software more adaptive. But they also change the nature of the dependency.
If an application asks an external model:
Which path should this request follow?
the model is no longer only helping an employee. It has become part of the application’s behaviour. That deserves different architectural thinking.
| Dimension | Deterministic application logic | AI-assisted decision capability |
|---|---|---|
| Behaviour | Explicit rules define the expected path | A model helps choose among allowed outcomes |
| Ownership | Logic primarily lives in company code | The company owns the workflow, but some behaviour may depend on an external model |
| Testing | Exact rules and outcomes can usually be asserted | Evaluations may need to test behaviour across representative cases |
| Provider change | Often an implementation replacement | May require behavioural comparison and revalidation |
| Fallback | A known deterministic path | Requires an intentionally designed fallback or escalation |
| Best fit | Stable rules with clear conditions | Situations where uncertainty or judgement adds genuine value |
Replacing the API may not replace the capability
It is tempting to think this can be solved by putting the provider behind an interface. That is good engineering practice, but it may not be enough. Imagine that an organization uses a decision model for several years.
Over time it builds:
- prompts or decision definitions
- evaluation datasets
- confidence thresholds
- escalation rules
- monitoring
- exception handling
- business processes based on the model’s behaviour.
Now another provider becomes more attractive. The API integration may be easy to replace. The behaviour may not be. The new model may classify edge cases differently.
Confidence scores may behave differently. Thresholds may need recalibration. Business users may need to validate the new outcomes. Regulated workflows may require fresh approval.
That means switching can become less like replacing a software library and more like changing part of the decision system. The dependency is therefore not necessarily the API. It is everything the organization has built around the behaviour of that AI.
Price is only one way dependency can surface
It would be too simplistic to assume that AI providers will continually increase prices once companies become dependent on them. There is no basis for making that general claim, and competition can push prices downward as well as upward.
The more important issue is that unit price and total dependency are different things.
A model can become cheaper while the company spends more overall.
Why?
Because it starts using AI in more places. A developer uses an agent for every coding task. Customer support becomes agent-assisted. Internal search uses models.
Security analysis uses models. Business workflows begin calling decision services. One AI interaction becomes thousands or millions of automated interactions.
TypeSafe makes this point explicitly in explaining the name Jev: greater efficiency can unlock much greater demand for machine intelligence. That is commercially positive when the extra usage creates value.
But it means organizations should not plan AI economics around today’s token price alone. The more important question is how much of the business will eventually depend on continuously purchasing external intelligence.
Designing dependency deliberately
This is familiar architecture thinking. Enterprise architects have dealt with dependency for decades through portability, service abstraction, disaster recovery, data ownership, open standards and exit planning. AI deserves the same discipline.
But one additional element matters because AI can replace knowledge as well as technology. If a company moves a database from one cloud to another, its engineers still understand databases.
If it moves a payroll SaaS platform, its HR team still understands payroll.
But if the organization gradually stops developing a capability because an AI system performs it, the company may eventually lose some of the expertise required to replace that system.
Technology dependency and capability dependency can develop together.
That does not mean companies should build everything themselves. Most organizations should not build frontier models or reproduce products that specialist vendors can provide far more efficiently.
The objective is simpler:
Use external intelligence without giving up unnecessary control of the capability around it.
That means keeping several things under the organization’s control.
Accessible text alternative for this figure
Six things an organization should keep under its control. One, business context: data, policies, terminology and domain knowledge. Two, evaluation: knowing what good looks like for any model. Three, decision boundaries: keeping deterministic rules where they are enough. Four, fallback behaviour: defining what happens when AI is unavailable or uncertain. Five, internal expertise: understanding the work well enough to evaluate the AI. Six, provider boundaries: avoiding provider-specific assumptions everywhere. The central principle is to use external intelligence without giving up unnecessary control of the capability around it. This is TechiesJournal analysis.
Business context
Company data, policies, terminology and domain knowledge should not exist only inside a vendor-specific implementation.
Evaluation
The organization should know what “good” looks like independently of whichever model is currently being used. If another model is introduced, the company should be able to test it against its own expectations.
Decision boundaries
Where deterministic rules are sufficient, they should remain deterministic. AI should be used where judgement or uncertainty genuinely adds value rather than replacing straightforward business logic simply because it can.
Fallback behaviour
Important workflows should define what happens if the AI service is unavailable, uncertain or outside its approved operating conditions.
Internal expertise
Employees should still understand the business and technical capability well enough to evaluate what the AI is doing.
Provider boundaries
Application architecture should avoid spreading provider-specific assumptions everywhere unnecessarily. None of these removes dependency. They make dependency manageable.
Exit planning should begin before exit is necessary
This may sound premature when an AI implementation is working well. That is precisely when it is easiest. Gartner recently made a related point while discussing vendor forward-deployed engineering for agentic AI.
Its concern is that organizations can achieve rapid early progress but fail to build enough internal capability to sustain and evolve the resulting system independently.
Its recommendation includes knowledge transfer, ownership and an exit strategy from the beginning rather than waiting until the relationship becomes difficult to change. I think that principle extends beyond forward-deployed engineering.
Before an organization makes an external AI service part of a critical capability, it should understand:
- What would we need to change if this service were unavailable?
- Which knowledge would we need internally?
- What would require revalidation?
- Which data and evaluations do we control?
- Could another model perform this role?
- What would remain operational while we changed it?
These are not questions to ask because we expect the provider to fail. They are questions to ask because responsible architecture assumes that technology changes.
Cost should be measured beyond consumption
This also changes how I think about AI FinOps. Tokens, model calls, agent runtime and tool usage still matter. But the economic picture is larger.
A mature organization may eventually need to understand:
Run cost
What does this AI workflow cost today?
Value
What work or business outcome does that spending produce?
Switching cost
What would it cost to move the capability elsewhere?
Capability cost
Which internal skills are becoming weaker because the AI performs the work? Those last two are harder to put into a dashboard. They may nevertheless matter more over the long term than a small difference in token pricing.
Perspective
The first stage of enterprise AI adoption was largely about capability. Can the model write useful code? Can it understand documents? Can the agent complete the task?
Can the decision model improve the workflow?
The next stage requires another consideration:
What happens to the organization as these systems become part of everyday work?
A successful AI system will naturally be used more. Teams will design processes around it. Employees will learn to rely on it. Software will begin expecting it to be available.
That is not failure. It is what successful technology adoption looks like. But success creates dependency.
The responsibility of architecture is not to eliminate that dependency. It is to make sure the organization understands it and retains enough control to adapt when technology, economics or business needs change.
For me, the principle is simple:
Use AI where it creates value. Let it remove unnecessary work. Let it improve decisions. But keep the knowledge, evaluation, architecture and operational control necessary to change how that intelligence is supplied.
The important distinction is not between companies that depend on AI and those that do not. Most serious organizations probably will. The distinction will be between dependency that developed accidentally and dependency that was designed deliberately.
Related reading: Building Agentic Systems: From Your First Agent to a Reliable System covers boundaries and reliability as agent autonomy increases, and Jev Explained: Why This AI Model Makes Decisions Instead of Writing Answers explains the decision model discussed above.
Sources and Further Reading
Source review: 5 October 2026.
- TypeSafe AI — Introducing System One Models & Jev. TypeSafe’s introduction to its early-access decision model and the reasoning behind designing AI specifically for structured software decisions. Published 15 September 2026. Performance figures in the source are vendor-reported.
- OpenAI — DevDay 2026 Recap: Decisions API. OpenAI’s description of the Decisions API for classification, routing and selecting actions from predefined choices, in limited preview on 29 September 2026. Availability may have changed since.
- Gartner — Gartner Predicts 70% of Enterprises Will Abandon Agentic AI Built by Vendor Forward-Deployed Engineering by 2028. Gartner’s analysis of forward-deployed AI engineering, with emphasis on knowledge transfer, ownership, internal capability and exit planning. The forecast concerns vendor forward-deployed engineering, not all enterprise AI.
- TechiesJournal — When AI Does the Junior Work, Who Develops the Next Generation of Professionals?. Earlier Author Perspective on what organizations risk losing when AI automates work that previously developed future professional capability.
- TechiesJournal — Building Agentic Systems: From Your First Agent to a Reliable System. Practical discussion of boundaries, reliability and operating considerations as agent autonomy increases.